
Definition: Tokens per second (TPS) is the rate at which a model streams its answer out — the throughput half of perceived AI speed, distinct from how long you wait before the first word appears.
TL;DR: Tokens per second measures generation speed after the reply starts. About 20 TPS already outpaces human reading, so it is fine for chat but slow for agents and long answers. TPS is set by memory bandwidth, active model size, batch size and the host, not by how "smart" the model is. One model can run 10x faster on one host than on another. Build an app with Taskade Genesis →
Tokens per second (TPS) in AI is the number of tokens, chunks of text about three quarters of an English word long, that a large language model writes each second once its answer starts. A model at 40 tokens per second writes about 30 words a second. TPS measures the speed of the stream, not the quality of the answer.
In databases and payments, TPS means transactions per second. In AI it almost always means output tokens per second, and this page uses it that way. The sections below answer the questions people ask most: whether 20 tokens per second is good, how tokens convert to words, how tokens per second differs from time to first token, how to measure it yourself, and why the same model streams 10x faster on one host than on another.
Is 20 Tokens Per Second Good?
Yes for reading, no for agents. At 20 tokens per second a model streams about three to four times faster than most people read (about 4 to 7 tokens per second), so a chat reply feels fine. But a 500-token answer takes 25 seconds to finish at 20 TPS, against 5 seconds at 100 TPS, and an agent that chains several calls waits on every one of them.
| Use case | Feels slow below | Comfortable | Why |
|---|---|---|---|
| Reading a chat reply | About 10 TPS | 20 to 50 TPS | You read at 4 to 7 TPS, so extra speed mostly helps skimming |
| Coding (code blocks, diffs) | About 30 TPS | 60 to 150 TPS | You skim code and wait for the full block before you run it |
| Agent loops | About 50 TPS | 100 TPS and up | Steps run in sequence, so every step waits on the one before |
| Reasoning models | About 50 TPS | 100 TPS and up, plus a short first-token wait | Hidden thinking tokens stream before the visible answer |
These ranges are rules of thumb from how people read and how agents chain calls, not an industry standard. The right target depends on answer length: a short reply at 20 TPS is done in a second or two, while a long report or a multi-step agent run is where a slow stream turns into minutes.
20 Tokens Per Second in Real Time
20 tokens per second is about 15 words a second, or about 900 words a minute. That is roughly four times the speed at which an adult reads silently, and six times the pace of normal speech. The bar chart below puts the numbers side by side, with one block for every 37.5 words per minute.
Words per minute (1 token is about 0.75 English words, 1 block = 37.5 wpm)

Typing, average person        ~40 wpm   █
Speaking, conversation       ~150 wpm   ████
Silent reading, adult        ~238 wpm   ██████
Model at 5 tokens/sec         225 wpm   ██████
Model at 10 tokens/sec        450 wpm   ████████████
Model at 20 tokens/sec        900 wpm   ████████████████████████
Model at 40 tokens/sec      1,800 wpm   ████████████████████████████████████████████████

Reading speed: Brysbaert (2019). Model rows: tokens/sec x 0.75 x 60.
So for a person who reads every word, 20 tokens per second already outruns the eye. The stream stops being "fast enough" only when nobody reads along: when you wait for a whole code block, a full report, or the next step of an agent loop.
Tier Table: Is 1, 5, 10, 40 or 100 Tokens Per Second Good
The same question comes up for every number, so here is one table for all of them. Words per minute assume about 0.75 English words per token.
| Tokens per second | Words per minute | For chat | For agents and long output | Where you see it |
|---|---|---|---|---|
| 1 | About 45 | Too slow, slower than reading | Unusable | A large model on a CPU, or one too big for GPU memory |
| 5 | About 225 | Borderline, about reading pace | Too slow | A big open-weight model on a laptop |
| 10 | About 450 | Usable floor | Slow | Large local models on consumer hardware |
| 20 to 25 | About 900 to 1,125 | Good, ahead of your eyes | Slow for long answers | Mid-size local models, busy hosted APIs |
| 40 to 50 | About 1,800 to 2,250 | Feels instant | Acceptable | A typical hosted API under load |
| 100 | About 4,500 | More than anyone can read | Good | Fast hosted tiers |
| 200 to 400 | About 9,000 to 18,000 | No visible difference | Very good | Fast GPU hosts with speculative decoding |
| 1,000 and up | 45,000 and up | No visible difference | Best | Custom inference chips and diffusion LLMs |
The top rows are where local hardware lives. On a laptop, model size decides the row: a small model can stream at 40 or more tokens per second, while a very large one can sit at 5. The bottom rows are hosted. Inception reported 1,068 tokens per second for its Mercury 3 diffusion model in October 2026, its own figure on NVIDIA GPUs, and a diffusion model refines many positions at once instead of writing one token at a time (MarkTechPost).
Answer Length and Wait Time at Each Speed
Answer length turns a speed into a wait. The table counts decode time only, the time after the first token appears, and the chart shows the middle column.
| Tokens per second | 100 tokens (short reply) | 500 tokens (long reply) | 2,000 tokens (report) | 8,000 tokens (long reasoning) |
|---|---|---|---|---|
| 10 | 10 s | 50 s | 3 min 20 s | 13 min 20 s |
| 20 | 5 s | 25 s | 1 min 40 s | 6 min 40 s |
| 40 | 2.5 s | 12.5 s | 50 s | 3 min 20 s |
| 100 | 1 s | 5 s | 20 s | 1 min 20 s |
| 400 | 0.25 s | 1.25 s | 5 s | 20 s |
The curve falls fast and then flattens. Going from 5 to 40 tokens per second saves 87 seconds on a 500-token answer. Going from 100 to 400 saves under 4.
That flattening is why speed upgrades feel huge at the low end and invisible at the high end for a single chat reply. For long outputs, reasoning models and agent chains, the right-hand columns of the table are the ones that matter.
Tokens Per Second Meaning: Converting Tokens to Words
Tokens per second means output tokens generated per second, and you convert it to words by multiplying by about 0.75 for English text. OpenAI's rule of thumb is that one token is about four characters, or about three quarters of a word, so 100 tokens is about 75 words (OpenAI Help Center). Multiply tokens per second by 45 to get words per minute.
| Tokens per second | Words per second | Words per minute | Pages per minute (500 words each) |
|---|---|---|---|
| 1 | 0.75 | 45 | 0.09 |
| 5 | 3.75 | 225 | 0.45 |
| 10 | 7.5 | 450 | 0.9 |
| 20 | 15 | 900 | 1.8 |
| 40 | 30 | 1,800 | 3.6 |
| 50 | 37.5 | 2,250 | 4.5 |
| 100 | 75 | 4,500 | 9 |
| 400 | 300 | 18,000 | 36 |
| 1,000 | 750 | 45,000 | 90 |
The 0.75 ratio is an English average, and three things move it:
- The text. Code, numbers, URLs and rare words split into more tokens per word, so the same tokens per second produces fewer words.
- The language. Many languages other than English use more tokens per word, so a stream in those languages carries fewer words per second.
- The tokenizer. Each model family has its own tokenizer, so 50 tokens per second on one model is not exactly 50 on another. Artificial Analysis counts every model's output with OpenAI's
o200k_basetokenizer so that its speed charts compare the same text (methodology).
Human Reading Speed in Tokens Per Second
Adults read English non-fiction silently at about 238 words per minute and fiction at about 260, according to a review of 190 studies by Marc Brysbaert (Journal of Memory and Language, 2019). At 0.75 words per token, that is about 5 to 6 tokens per second.
| Activity | Words per minute | Tokens per second |
|---|---|---|
| Typing, average person | About 40 | About 0.9 |
| Speaking, normal conversation | About 150 | About 3.3 |
| Silent reading, non-fiction | About 238 | About 5.3 |
| Silent reading, fiction | About 260 | About 5.8 |
| Model at 20 tokens per second | About 900 | 20 |
So any model above about 6 tokens per second writes faster than you read it. Skimming is faster than careful reading, which is why people still feel a difference between 20 and 50 tokens per second when they scan for the one line they need.
Time to First Token vs Tokens Per Second
Time to first token (TTFT) is the wait before a reply starts, and tokens per second is the speed of the stream after that. People say "fast AI" and mean either one, but they come from different phases of inference and have different causes.
| Metric | What it measures | Set by | What it feels like |
|---|---|---|---|
| Time to first token (TTFT) | Delay before the first word | Prefill — reading your prompt | The pause after you hit enter |
| Tokens per second (TPS) | Rate of the stream after that | Decode — memory bandwidth | How fast text scrolls |
A long prompt hurts TTFT. A long answer hurts total time via TPS. Optimizing the wrong one is a common mistake: attaching a large document slows the pause, not the stream.
Two clocks, two causes. The first is about what you sent; the second is about what you get back.
Reasoning models add a third wait between the two clocks. A reasoning model writes hidden thinking tokens before the first token of the visible answer, and those tokens stream at the same decode speed. So the first chunk can arrive in under a second while the first answer word arrives many seconds later. Artificial Analysis shows this on Kimi K3, which always reasons: its fastest host returned a first chunk in about 0.7 seconds but the first answer token in about 5.4 seconds (fetched 2026-10-20). When you compare reasoning models, compare time to first answer token, not time to first token.
Every request passes through the same states. A timer that stops at the first token of any kind ends at the edge of Prefill. A timer that waits for the first answer token also counts all of Thinking.
End-to-End Latency: The Number You Actually Wait On
End-to-end latency is the full time from sending a request to receiving the last token, and it equals time to first token plus output tokens divided by tokens per second. That one formula ties the three speed numbers together, and it shows which one to fix: a long prompt grows the first term, a long answer grows the second.
One request: 10,000-token prompt, 500-token answer, illustrative numbers

0.0 s       1.0 s                                                    26.0 s
  |-----------|-------------------------------------------------------|
  [   TTFT   ][ decode: 500 tokens at 20 tokens/sec = 25.0 s           ]
   queue and   first     ...one new token about every 50 ms...      last
   prefill     token                                                token

End-to-end latency = TTFT + output tokens / TPS
                   = 1.0 s + 500 / 20  = 26.0 s
Same answer at 100 tokens per second:
                   = 1.0 s + 500 / 100 =  6.0 s
The sequence below shows where each clock starts and stops inside one call to a model host.
TTFT covers the network, the queue and prefill. Tokens per second covers only the loop. End-to-end latency covers all of it.
Five numbers show up on speed dashboards and in vendor claims. They are easy to mix up, so here they are side by side.
| Metric | Also called | How it is computed | What it tells you |
|---|---|---|---|
| Time to first token | TTFT | First-token time minus send time | How long the pause is |
| Output tokens per second | TPS, output speed | Output tokens divided by seconds after the first token | How fast the text streams |
| Time per output token | TPOT, inter-token latency | 1 divided by TPS, so 20 ms means 50 TPS | The gap between two tokens |
| End-to-end latency | Total response time | TTFT plus output tokens divided by TPS | How long the whole answer takes |
| System throughput | Aggregate tokens per second | Sum of every stream on the hardware | How much a host produces per GPU |
Per-User vs System Tokens Per Second
Per-user tokens per second is the speed of one stream. System tokens per second is the total across every stream a GPU or rack serves at once. A server that streams 40 tokens per second to each of 64 users produces 2,560 tokens per second in total, and a vendor can quote either number.
Only the per-user number tells you how fast your own answer will stream. The system number tells you how cheaply a host can sell tokens, which is the subject of inference cost and the Inference-as-a-Service business. When a figure looks impossible for one stream, check whether it is a system number.
What Is a Good Tokens Per Second?
A good tokens-per-second rate depends on who reads the stream. For a person in a chat, about 30 to 50 tokens per second per user feels fast. For agent chains and long outputs, a higher rate is better, because each step waits on the step before it.
| Reader or workload | Tokens per second | Note |
|---|---|---|
| Human silent reading | About 4 to 7 | Adults read English non-fiction at about 238 words per minute (Brysbaert, 2019), at about 0.75 words per token |
| Chat, a person watching | About 30 to 50 per user, or more | The text appears faster than you can read it |
| Typical GPU host, 2026 | Tens to a few hundred per user | Changes with the model, the host, and the load |
| Groq, gpt-oss-120b | About 474 per user | Artificial Analysis measurement |
| Cerebras, gpt-oss-120b | About 1,600 to 1,800 per user | Artificial Analysis readings, 2026 |
The rate is a property of the host, not only of the model. The same open-weight model can stream several times faster on one provider than on another. The Inference-as-a-Service guide explains why per-user speed and cost per token pull against each other.
Photo: Avivweinstein / Wikimedia Commons / CC BY-SA 4.0
The fastest rows in that table come from chips built for inference. Groq and Cerebras keep model weights in on-chip SRAM instead of external HBM, which removes most of the memory wait that limits a GPU during decode. The trade-off is coverage: a new model architecture takes time to reach custom silicon, so the newest open-weight models usually appear on GPU hosts first. The AI data centers guide covers the hardware side, and NVIDIA's history covers how the GPU became the default.
ChatGPT Tokens Per Second
OpenAI does not publish a fixed tokens-per-second figure for ChatGPT. The rate changes with the model, the reasoning setting, and the load at that moment. A reasoning model also writes hidden reasoning tokens before the visible answer, so the wait before the first visible word is longer. To measure the rate, time a long answer and divide the output tokens by the seconds after the first token appears.
What Counts as Fast
For a human reading a reply, the useful threshold is lower than people assume — comfortable reading speed is only a handful of tokens per second, so anything above roughly 40 TPS reads as instant.
Where higher TPS genuinely matters is where no human is reading in real time:
- Long-form generation, where total time is dominated by output length.
- Agentic loops, where one instruction triggers many model calls in sequence and each one's latency compounds.
- Reasoning models, which generate substantial internal reasoning before the visible answer.
The compounding is worth making concrete. A five-step agent chain in which each step produces 600 tokens spends 75 seconds in pure decode at 40 TPS, but 25 seconds at 120 TPS — the same work, the same model calls, 50 seconds apart in feel. No single step looked slow; the chain was.
Five-step agent chain, 600 output tokens per step (decode time only)

At 40 TPS    [ 15 s ][ 15 s ][ 15 s ][ 15 s ][ 15 s ]   = 75 s
At 120 TPS   [5 s][5 s][5 s][5 s][5 s]                  = 25 s

Add each step's time to first token on top. With a 1 s TTFT per step,
the chain takes 80 s at 40 TPS and 30 s at 120 TPS.
Two levers shorten a chain without a faster model. Steps that do not depend on each other can run at the same time, which multi-agent systems do by design. And a cap on output length cuts decode time directly, which is why good prompt engineering asks for the shortest useful answer. The agent builders guide and multi-agent platforms roundup show both in practice.
Interactive vs Batch: Two Different Targets
"How fast is fast enough?" has two answers, because there are two kinds of consumer of the stream — a person watching it, and a pipeline waiting on it.
| Workload | What matters | Practical target |
|---|---|---|
| Chat, a human reading | Perceived smoothness | ~20–50 TPS per user, plus a short first-token wait |
| Voice assistants | The pause before speech | Time-to-first-token above all; TPS barely matters |
| Agent chains and reasoning | Total wall-clock across many calls | As high as the hardware allows |
| Batch jobs (digests, backfills, evals) | Cost per token only | None — overnight is fine, so providers sell discounted batch tiers |
The two targets pull against each other on shared hardware: packing more users into a batch raises the total tokens a chip produces while lowering each individual stream. Provider-scale numbers make the gap vivid — Microsoft quotes about 865,000 tokens per second for a single rack in its Fairwater AI datacenters, an aggregate figure thousands of interactive streams wide, not a speed any one user sees.
The practical takeaway: match the work to the tier. Anything a person is not watching — a nightly digest, a weekly report, a data backfill — belongs in scheduled automations rather than an interactive session, where it costs less and competes with nobody.
What Sets the Number
Four things, and only one of them is about the model's capability:
- Memory bandwidth. Every token requires reading the model's weights out of memory. This is the hard ceiling.
- Model size. More parameters means more bytes read per token, so larger models generate more slowly at equal hardware.
- Batch size. Serving many users at once raises total throughput but can lower any single user's TPS — a genuine tension between cost efficiency and individual latency.
- Context length. A larger KV cache means more state read per token, so long conversations stream more slowly than short ones.
Architectural choices push against this. Mixture-of-experts models activate only part of the network per token, reducing bytes read. Speculative decoding drafts several tokens with a small model and verifies them with the large one, effectively producing more than one token per expensive pass.
When an AI tool feels slow, the first job is to find out which of the speed numbers is the slow one. The fix for each is different, and the flow below sorts them.
For the first branch, prompt caching and a tighter context window help most. For the second, model routing sends easy requests to a faster model. For the third, the work itself needs a new shape, which is where context engineering and shorter outputs pay off.
Measuring Tokens Per Second Yourself
To measure tokens per second, stream a long answer, record when the first and the last token arrive, and divide the output tokens minus one by the seconds between those two moments. Measure time to first token on the same run, and repeat the test several times, because a hosted model's speed changes with load.
Follow these steps for any API that streams:
- Pick a prompt that forces a long answer, at least 500 output tokens, so the first-token wait does not dominate the result.
- Turn streaming on. Without streaming you only see the total time, and you cannot separate TTFT from decode.
- Record three timestamps: when you send the request, when the first content token arrives, and when the last token arrives.
- Read the output token count from the API's usage field, not from a word count. Different models split text differently.
- Compute the three numbers: TTFT is first minus send. Tokens per second is (output tokens minus 1) divided by (last minus first). End-to-end latency is last minus send.
- Repeat 5 to 10 times at different hours and use the median, not the best run.
- Keep the prompt length fixed when you compare hosts. Artificial Analysis uses a 10,000-token prompt by default, so a short test prompt will not match its numbers.
The Python script below does steps 2 to 5 for any OpenAI-compatible API. Point base_url at another host to compare providers.
import time
from openai import OpenAI

client = OpenAI()  # add base_url="https://..." for another OpenAI-compatible host
sent = time.perf_counter()
first = None
usage = None

stream = client.chat.completions.create(
    model="YOUR_MODEL_ID",
    messages=[{"role": "user", "content": "Explain how a jet engine works in about 500 words."}],
    stream=True,
    stream_options={"include_usage": True},
)
for chunk in stream:
    if first is None and chunk.choices and chunk.choices[0].delta.content:
        first = time.perf_counter()
    if chunk.usage:
        usage = chunk.usage
last = time.perf_counter()

tokens = usage.completion_tokens
print(f"TTFT: {first - sent:.2f} s")
print(f"Tokens per second: {(tokens - 1) / (last - first):.1f}")
print(f"End-to-end: {last - sent:.2f} s for {tokens} tokens")
On a reasoning model, the usage count includes the hidden reasoning tokens, while the first content token arrives only after the thinking ends. That makes the computed rate look too high. Test reasoning models with reasoning set to its lowest level, or subtract the reasoning tokens that the usage details report.
Measuring Tokens Per Second on a Local Model
Local runners print the speed for you. Each one reports prefill speed and decode speed separately, and decode speed is the number to compare with the tables on this page.
| Tool | How to see the speed | What it reports |
|---|---|---|
| Ollama | Run ollama run MODEL --verbose |
Prompt eval rate and eval rate, in tokens per second |
| llama.cpp | Run llama-bench -m model.gguf |
pp (prompt processing) and tg (text generation) tokens per second |
| LM Studio | Read the stats line under each reply | Tokens per second and time to first token |
| vLLM | Run its serving benchmark against your server | TTFT, time per output token and throughput |
On a local machine, the GPU memory bandwidth and the model's file size predict the result well, which is the subject of the next two sections. If the model does not fit in GPU memory and part of it runs from system RAM, decode speed drops sharply, because system RAM moves data far more slowly than GPU memory.
Reading Published Benchmarks Carefully
TPS figures are only comparable when three things are stated: batch size, context length, and hardware. A number measured at batch size 1 on an empty context is a best case that no production system operates in. If a benchmark omits those, it is a marketing figure rather than a measurement.
There is also a hard physical ceiling to sanity-check any claim against. Single-stream generation cannot read weights faster than the memory allows: a 70 GB set of 8-bit weights over an H100's 3.35 TB/s of bandwidth caps one stream near 48 tokens per second, no matter the software. On an NVIDIA B300, with about 8 TB/s of HBM bandwidth per GPU, the same 70 GB caps one stream near 114 tokens per second. Claims far above that for a dense model of that size are describing batched aggregate throughput, speculative decoding, a mixture-of-experts architecture reading fewer bytes per token — or a smaller model than implied.
A short checklist for any tokens-per-second claim you read:
- Per user or system? A system figure adds up every stream on the hardware.
- Does it include time to first token? Artificial Analysis output speed does not. It counts only the stream after the first token.
- How long were the prompt and the answer? A 100-token prompt and a 10,000-token prompt give different numbers on the same host.
- Which tokenizer? Tokens from two model families are not the same size.
- When was it measured? Hosted speeds change from day to day, so an undated number is already old.
Memory Bandwidth Ceiling Math: H100 vs B300
The ceiling on single-stream decode speed is memory bandwidth divided by the bytes read for each token. An NVIDIA H100 moves 3.35 TB/s from its HBM, and an NVIDIA B300 moves about 8 TB/s. So the same model can stream up to about 2.4 times faster on a B300, before any software tricks.
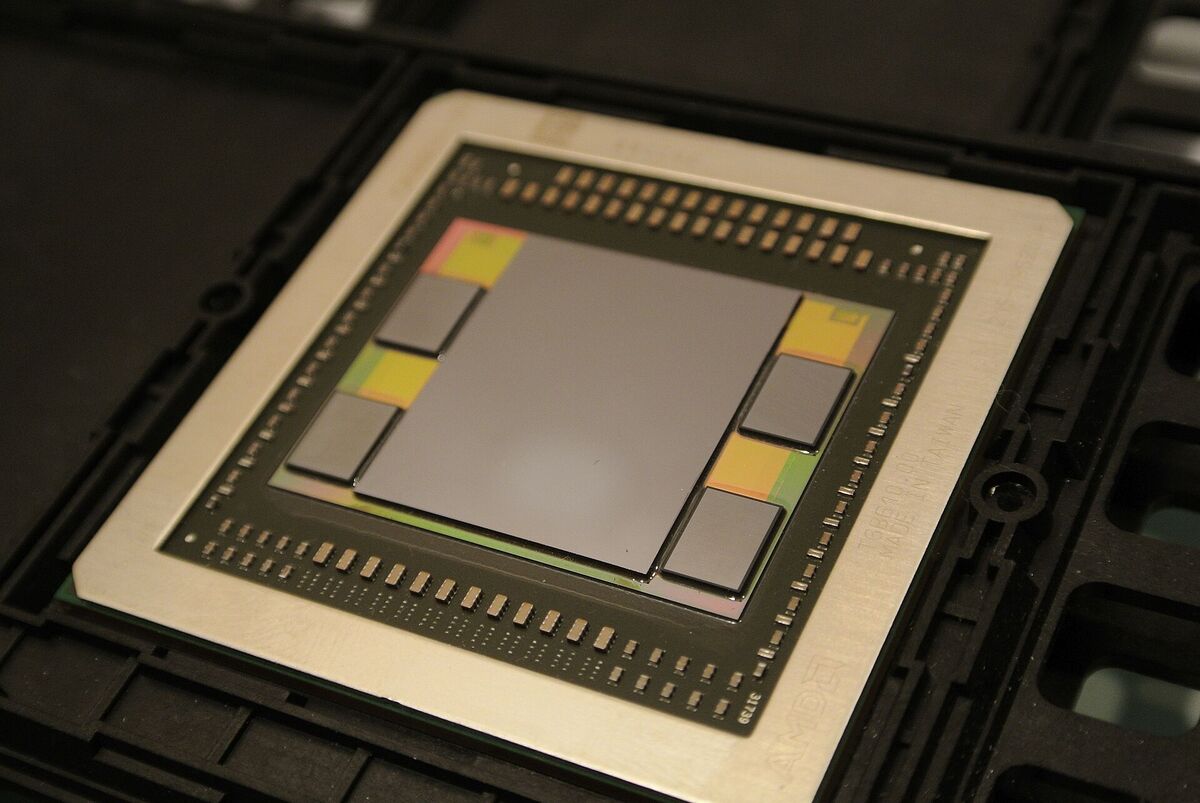
Photo: C. Spille/pcgameshardware.de / Wikimedia Commons / CC BY-SA 4.0
Each new token needs every active weight read out of memory once, and the math units wait while that happens. That is why decode is called memory-bandwidth-bound, and why the memory bandwidth number on a spec sheet predicts tokens per second better than the FLOPS number does.
Ceiling on single-stream decode speed

  tokens per second  <=  memory bandwidth  /  bytes read per token

  70B dense model, 8-bit weights  ->  about 70 GB read per token
    H100 :  3,350 GB/s / 70 GB  =  about  48 tokens per second
    B300 :  8,000 GB/s / 70 GB  =  about 114 tokens per second

  Same model, 4-bit weights       ->  about 35 GB read per token
    H100 :  3,350 GB/s / 35 GB  =  about  96 tokens per second
    B300 :  8,000 GB/s / 35 GB  =  about 229 tokens per second

  Real engines land below these ceilings. KV cache reads, kernel
  overhead and GPU-to-GPU traffic each take a share.
The table runs the same math for more model sizes. A model that does not fit on one GPU is split across eight with tensor parallelism, so the eight GPUs read their shares at the same time and their bandwidth adds up.
| Model and weight precision | Bytes read per token | H100 ceiling | B300 ceiling |
|---|---|---|---|
| 8B dense, 8-bit | About 8 GB | About 419 tokens/s | About 1,000 tokens/s |
| 8B dense, 4-bit | About 4 GB | About 838 tokens/s | About 2,000 tokens/s |
| 70B dense, 8-bit | About 70 GB | About 48 tokens/s | About 114 tokens/s |
| 70B dense, 4-bit | About 35 GB | About 96 tokens/s | About 229 tokens/s |
| 405B dense, 8-bit, on 8 GPUs | About 405 GB | About 66 tokens/s | About 158 tokens/s |
| Kimi K3 MoE, about 104B active, on 8 GPUs | About 55 GB | Does not fit on 8 H100s | About 1,160 tokens/s |
The ratio stays the same in every column: the B300 ceiling is about 2.4 times the H100 ceiling, because only the bandwidth changed.
Three things let real systems beat a naive reading of this table. A mixture-of-experts model reads only its active experts, which is how Kimi K3 lands in the last row. Speculative decoding checks several drafted tokens in one read of the weights. And quantization to 4-bit or lower halves the bytes again. Batching does not raise the single-stream ceiling, but it lets one read of the weights serve many users, which is why system throughput can be thousands of times higher than any one stream.
Same Model, Different Speed: Kimi K3 Across Hosts
The same open-weight model can stream about 10x faster on one host than on another. Kimi K3, the open-weight model from Moonshot AI, is a clear case: on Artificial Analysis the fastest host streamed about 422 output tokens per second, while Moonshot's own first-party API streamed about 42. The weights are identical, so the gap comes from how each host serves them.
| Host (Artificial Analysis label) | Output speed (tokens/s) | First chunk (s) |
|---|---|---|
| LithosAI (Ultra Chat) | About 422 | 0.70 |
| Parasail | About 198 | 1.16 |
| Nebius | About 192 | 1.07 |
| Amazon Bedrock | About 142 | 1.33 |
| Fireworks | About 112 | 0.97 |
| Baseten | About 96 | 0.95 |
| Together AI | About 57 | 0.96 |
| Kimi (Moonshot first-party) | About 42 | 3.69 |
| Inco | About 32 | 4.24 |
Source: Artificial Analysis, Kimi K3 providers, median over the past 72 hours with 10,000 input tokens, fetched 2026-10-20. These are live measurements, and they change from day to day. A selection of the hosts listed.
Same weights, a 13x spread from the fastest host to the slowest on one day. Seen this way, "how fast is Kimi K3" has no single answer. It depends on where the model runs.
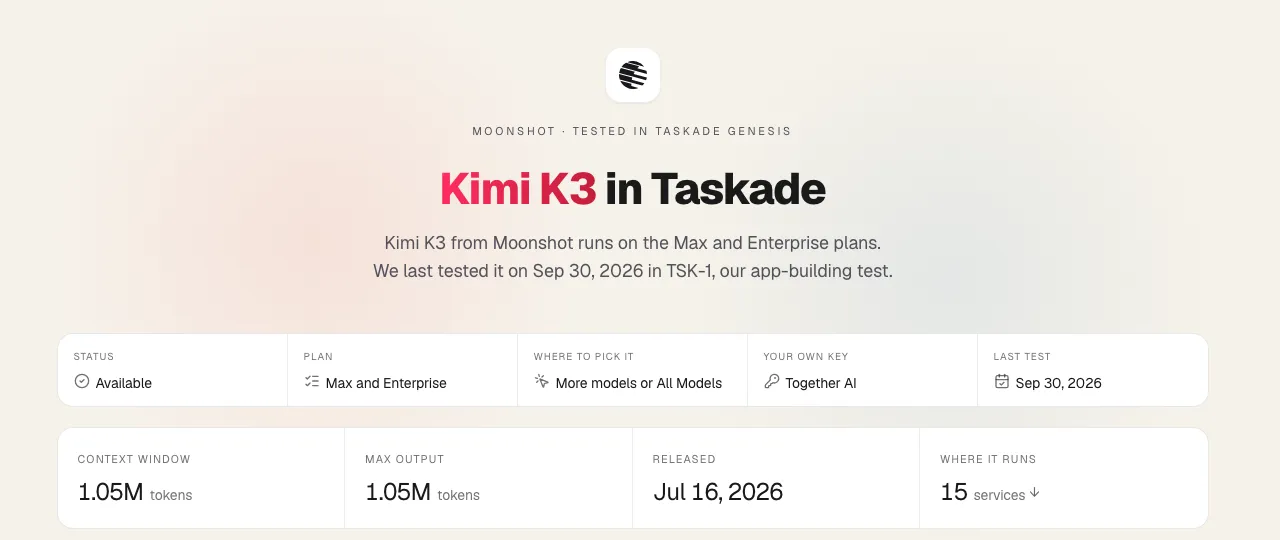
The Kimi K3 model page lists the services that serve the model, and the Moonshot lab page lists the rest of the family. The spread on Artificial Analysis is the reason a "Where it runs" list matters: picking a host is picking a speed. For the company behind the model, see the Moonshot AI and Kimi history, and for head-to-head results see Kimi vs Claude, Kimi vs DeepSeek and Qwen vs Kimi.
A 2.8-trillion-parameter model decodes like a 104B model
Kimi K3 has about 2.8 trillion parameters in total, but it is a mixture-of-experts model. Each token runs through 16 of its 896 routed experts plus 2 shared experts, so only about 104 billion parameters (about 3.7%) work on any one token. Decode is bound by memory bandwidth, and only those active weights stream out of memory for each new token. With the routed experts in the native MXFP4 format (attention and the shared experts stay at higher precision), that is on the order of 55 GB per token instead of the full checkpoint.
The full checkpoint still has to sit in GPU memory. At production batch sizes, every expert is active for some user at any instant, and swapping experts in and out of memory would break the latency a host promises. So the whole checkpoint of about 1.56 TB stays resident. That fits on one node of 8 NVIDIA B300 GPUs (288 GB of HBM3e each, about 2.3 TB in total). It does not fit on 8 B200 GPUs (180 GB each, 1.44 TB) or on 8 H100 GPUs (80 GB each, 640 GB).
A rough ceiling shows how much the active-weight trick matters. Eight B300 GPUs read about 64 TB/s together. At about 55 GB per token, one stream tops out near 1,160 tokens per second before cache reads and GPU-to-GPU traffic. If all 1.56 TB streamed per token, the same node would top out near 40.
The levers each host controls
- Hardware. Decode is bandwidth-bound, so the HBM speed sets the ceiling. A B300 moves about 8 TB/s per GPU; an H100 moves 3.35 TB/s. A host on older chips also needs more GPUs just to hold the weights.
- Speculative decoding. A small draft model or head proposes several tokens, and the full model checks them in one pass. Methods include EAGLE-3, DFlash, a block-diffusion drafter, and DSpark, a confidence-scheduled semi-autoregressive drafter. A drafter trains on the target model's hidden states, so it can only exist after the model runs in production.
- Batch size. More users per GPU raises the host's total output and lowers each user's speed. A tier sold on speed can keep its batches small.
- Parallelism. Tensor parallelism across 8 GPUs (TP8) splits every layer and gives the best single-user latency. Adding expert parallelism (EP) places whole experts on specific GPUs and favors throughput, and hosts rebalance hot experts at run time.
- Always-on reasoning. Kimi K3 always thinks before it answers. A fast stream still spends seconds on hidden thinking, so time to first answer token matters as much as output speed.
Context length behaves differently on Kimi K3, too. Only 24 of its 93 layers use attention with a per-token KV cache (about 13.5 KiB per token in FP8). The other 69 use Kimi Delta Attention, a linear-attention layer that keeps a fixed-size state per sequence. So a long conversation slows decode less than it does on a model where every layer grows its cache, even at the full 1,048,576-token window. The trade-off: a cached prompt prefix is reused less precisely, because the linear layers resume only from the nearest saved state.
Baseten, one of the hosts in the table, explains in the talk below how a trillion-parameter model is split across GPUs and why total parameters, not active ones, decide how much GPU memory a host needs.
Picking a Model When Hosts Differ in Speed
| If you need | Look at | Why |
|---|---|---|
| Fast chat replies | Output speed and time to first answer token | Both shape what a person sees |
| Fast agent chains | Output speed first | Decode time repeats at every step |
| Long documents in the prompt | Time to first token at 10,000+ input tokens | Prefill grows with the prompt |
| The lowest cost per task | Price per token, then speed | A slow host can still be the cheapest |
| Steady speed all day | The 72-hour median, not a single best run | Load changes speed hour by hour |
A host listing is a snapshot, not a contract. Re-check the numbers before you commit a workload, and measure your own prompts with the steps in How to Measure Tokens Per Second Yourself.
Where TPS Actually Reaches You
If you use a hosted platform, you never pick a TPS figure. You pick a speed and depth, and the platform picks the model. In Taskade the model menu offers TSK-Auto and the TSK rungs across frontier models from top AI labs:
| Setting | Best for | Plan |
|---|---|---|
| TSK-Auto | Picks a model for each task (default) | Every plan |
| TSK-Instant | Quick edits, lowest credit use | Every plan |
| TSK-Standard | Everyday apps and tasks | Paid plans |
| TSK-Thinking | Bigger apps that need more care | Paid plans |
| TSK-Reasoning | Complex apps and the deepest thinking, uses more credits | Business and up |
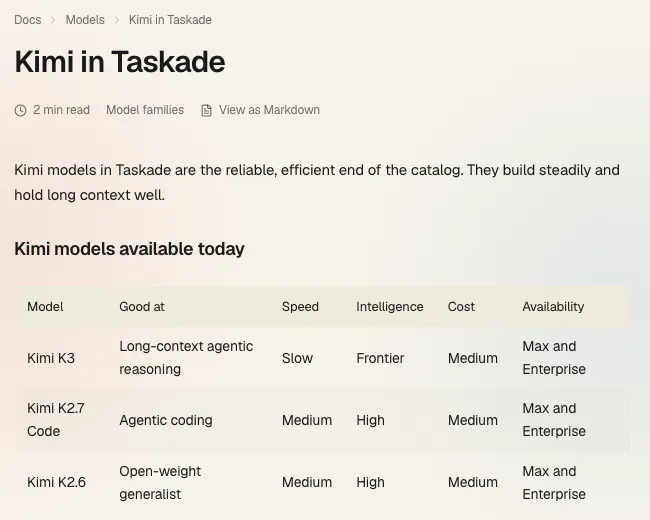
AI agents running multi-step work feel the choice most, since their latency compounds per call. Work with no human watching runs as automations on triggers and schedules, where throughput is invisible and only the outcome matters. Choosing depth per task is covered in thinking modes, and the Custom Engine docs list each model with its speed, intelligence and cost.
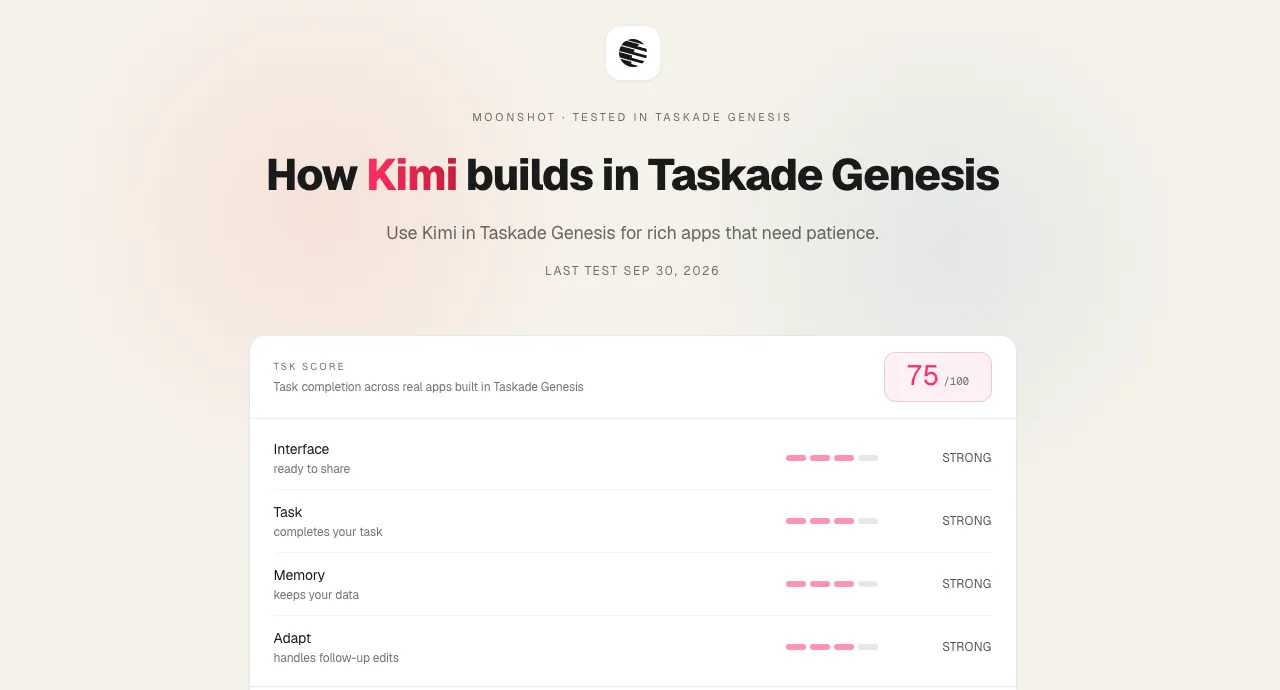
Speed and build quality are different tests. Taskade's TSK-1 test builds real apps in Taskade Genesis with each model family. Its verdict on Kimi reads: "Builds more than almost any model and finishes later than all of them." A slow stream can still produce the richest app, so the right pick depends on whether you are waiting at the screen. The TSK results hub has every family, and Kimi on TSK-1 has the full Kimi run.
Pick the host with your own key (BYOK)
Taskade buys tokens from model hosts, so the speed you see on Taskade credits is the speed of the host Taskade uses. The Kimi model docs rate Kimi K3 as Slow, with frontier intelligence, and it runs on Taskade credits on Max and Enterprise. With your own API key (BYOK), you pick the host:
- An OpenAI, Anthropic or Google Vertex AI key serves custom AI agents, Ask Agent and built-in AI automation steps on Pro and up. Claude runs in Taskade only on your own Anthropic key.
- An xAI, Groq, Mistral or Together AI key serves custom agents and Ask Agent on Business and up. A Together AI key can pick Kimi K3, and a Groq key runs the open-weight GPT OSS models at Groq's own speed.
- Your plan includes agent steps on your own key each month, and each agent step after that uses one fixed step fee in Taskade credits. On Pro and up, Taskade EVE builds and edits run on your key too when you pick a model under Your keys, with the same step fee for each step. TSK-Auto and the TSK tiers stay on Taskade credits.
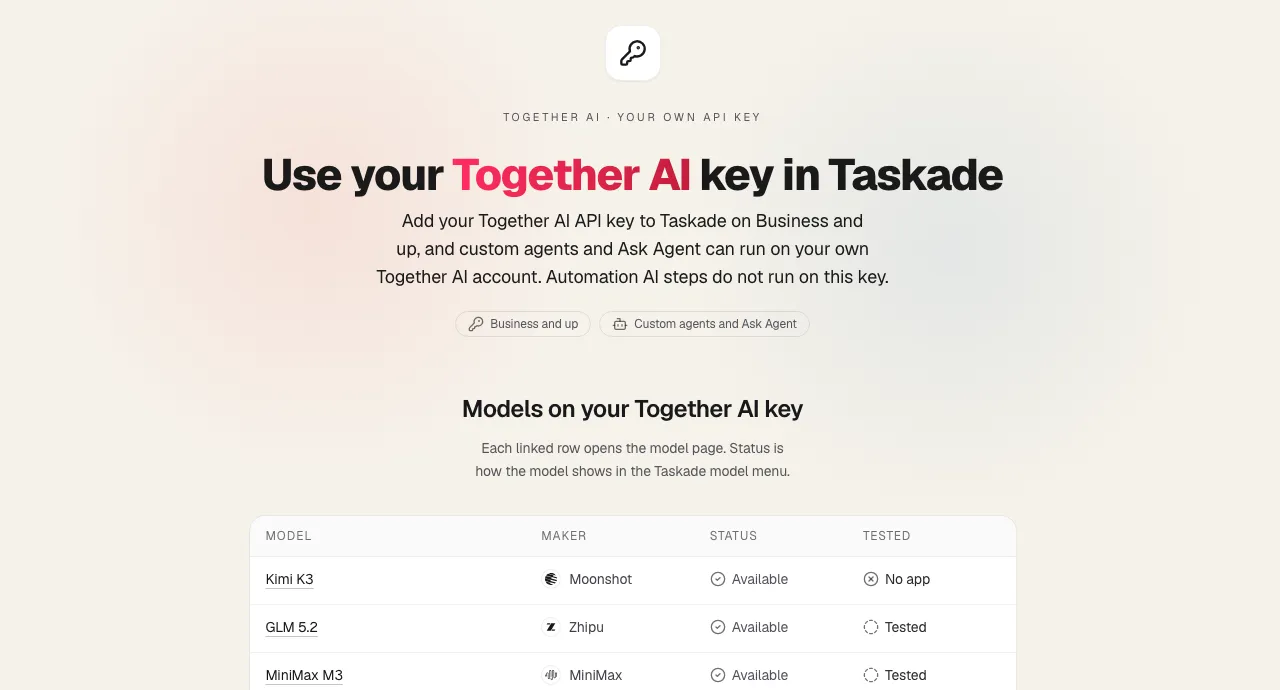
Automations have a second lane. Provider steps call a model directly inside a workflow: OpenAI, Anthropic Claude and Google Gemini steps need Pro and up, and Groq and OpenRouter steps need Business and up. Your provider bills each model call, and each step uses one fixed step fee in Taskade credits, the same for every model. To make a built-in AI step use your key, set a specific model rather than TSK-Auto. Bring your own AI keys in automations covers the setup.
Where your key sets the speed (Taskade, 2026-10-20)

  Custom agent chat / Ask Agent
    OpenAI, Anthropic, Google Vertex AI key ....... Pro and up
    xAI, Groq, Mistral, Together AI key ........... Business and up
    -> speed = your provider's host, a fixed step fee after the included steps

  Automation provider steps
    OpenAI, Anthropic Claude, Google Gemini ....... Pro and up
    Groq, OpenRouter .............................. Business and up
    -> speed = your provider's host, one fixed step fee in credits

  Taskade Genesis app building, Taskade EVE chat
    -> always on Taskade credits, Taskade picks the host
Model providers lists which models each key can serve, with pages such as Together AI and Groq, and Bring Your Own AI Keys (BYOK) walks through the setup. Plans and credit allowances are on the pricing page: Pro is $10 a month and Business is $25 a month, both billed annually. For a wider view, see AI builders with BYOK and how AI inference works.
Related Concepts
- Memory Bandwidth — the ceiling
- GPU · HBM — the hardware behind the ceiling
- Inference — where TTFT and TPS come from
- KV Cache · Context Window
- Test-Time Compute · Reasoning Effort
- Inference Cost · Model Routing
- Inference-as-a-Service: the business that sells this speed
- Token · Tokenizer — the unit being counted
- Prompt Caching — cuts time to first token
- Reasoning Models · Next-Token Prediction
- Model Parameters · Open-Source Models
- Multi-Agent Systems · Agent Loop
Frequently Asked Questions About Tokens Per Second
What does TPS mean in AI?
In AI, TPS means tokens per second: how many tokens a language model writes each second after its answer starts. A token is a chunk of text of about three quarters of an English word. Outside AI, TPS usually means transactions per second, which is unrelated.
How fast is 20 tokens per second?
20 tokens per second is about 15 words a second, or about 900 words a minute. That is about four times faster than adults read silently (about 238 words per minute). A 100-token reply finishes in 5 seconds, and a 500-token answer in 25 seconds.
Is 40 tokens per second good?
Yes. 40 tokens per second is about 1,800 words a minute, so a chat reply appears faster than anyone can read it, and most people perceive it as instant. 40 to 50 tokens per second is also workable for coding. Long agent chains still benefit from 100 or more.
How many words per minute is a token per second?
One token per second is about 45 words per minute in English, because a token averages about 0.75 words. Multiply tokens per second by 45 to get words per minute: 20 tokens per second is about 900 words per minute, and 100 tokens per second is about 4,500.
What is human reading speed in tokens per second?
About 5 to 6 tokens per second. Adults read English non-fiction silently at about 238 words per minute and fiction at about 260 (Brysbaert, 2019), which works out to about 5.3 and 5.8 tokens per second at 0.75 words per token.
How do you calculate tokens per second?
Divide the output tokens by the seconds spent generating them, after the first token appears: tokens per second = (output tokens minus 1) divided by (time of last token minus time of first token). To predict a wait, use end-to-end latency = time to first token + output tokens divided by tokens per second.
How do you measure tokens per second?
Stream a long answer, record the time you send the request and the times the first and last tokens arrive, and read the output token count from the API usage field. Repeat several runs and take the median. Local tools report it directly: Ollama with --verbose, llama.cpp with llama-bench, and LM Studio under each reply.
What is a good time to first token?
For chat, under about one second feels responsive, and a few seconds feels like a pause. Time to first token grows with prompt length, queueing and, on reasoning models, thinking time. On Artificial Analysis, Kimi K3 hosts returned a first chunk in about 0.7 to 4.2 seconds with a 10,000-token prompt (fetched 2026-10-20).
What is the difference between per-user and system tokens per second?
Per-user tokens per second is the speed of one stream, the number you feel. System tokens per second adds up every stream on the hardware: a server sending 40 tokens per second to each of 64 users produces 2,560 in total. Vendor headlines often quote the system number.
Is 20 tokens per second fast enough for chat?
For reading a chat reply, yes. 20 tokens per second is about three to four times faster than most people read, so the text keeps ahead of your eyes. For agents and long answers it is slow: a 500-token answer takes 25 seconds at 20 tokens per second, and an agent that chains several calls waits on each one.
What is a good tokens per second for an LLM?
As a rule of thumb, 20 to 50 tokens per second is comfortable for chat, 60 to 150 for coding, and 100 or more for agent loops and reasoning models. For a person reading a reply, anything above roughly 40 tokens per second reads as instant, because comfortable human reading speed is well below that. Higher rates matter most for long outputs, agent loops, and reasoning models, where total generation time rather than perceived streaming speed is what you are waiting on.
Why is the same model faster on one provider?
Because speed depends on how a host serves the weights, not only on the weights. Hosts differ in GPU memory bandwidth, speculative decoding, batch size and how they split the model across GPUs. On Artificial Analysis, Kimi K3 streamed about 422 tokens per second on its fastest host and about 42 on Moonshot's own API (fetched 2026-10-20), roughly a 10x spread for identical weights.
How many tokens per second does ChatGPT generate?
OpenAI does not publish a fixed figure. The ChatGPT rate changes with the model, the reasoning setting, and the load. A reasoning model also spends time on hidden reasoning before the visible answer starts. To measure the rate, divide the output tokens of a long answer by the seconds after the first token appears.
What is the difference between tokens per second and time to first token?
Time to first token is the delay before the reply starts, set by the prefill phase reading your prompt. Tokens per second is the rate of the stream afterwards, set by the decode phase. A long prompt slows the first; a long answer is governed by the second.
Why do larger models generate more slowly?
Because generating each token requires reading the model's parameters out of memory, and more parameters means more bytes to read. Generation speed tracks memory bandwidth divided by model size far more closely than it tracks raw arithmetic throughput. For a mixture-of-experts model, the size that counts is the active part: Kimi K3 has about 2.8 trillion parameters but reads only about 104 billion per token.
Does a higher tokens-per-second rate mean better answers?
No. It is a throughput property of the hardware and model size, not a measure of quality. A smaller model will usually stream faster than a larger one while producing less capable output, which is exactly the trade-off model routing is designed to make per request.
Why does my AI stream more slowly during busy hours?
Because you share hardware with everyone else. Serving systems batch concurrent requests to keep the chip efficient, and a fuller batch divides the same memory bandwidth across more streams — total throughput rises while each individual stream slows. Your slower afternoon stream is the provider's cost efficiency working as designed.
What is batch inference?
Running requests that nobody is waiting on — digests, backfills, evaluations — grouped together for maximum hardware efficiency instead of minimum latency. Providers typically discount it heavily, often around half the interactive price, because dense batches extract far more tokens per GPU-hour than latency-sensitive traffic can.
Does streaming make AI generate faster?
No. Streaming shows tokens as they are produced instead of waiting for the full answer, so the wait feels shorter, but the generation rate is identical. What streaming genuinely improves is time-to-usefulness: you can start reading, and often stop the generation early, which does save real time and tokens.
Further Reading
- AI Inference Explained
- Inference-as-a-Service: How AI Is Sold in 2026
- AI Builders With Bring Your Own Key (BYOK)
- No-Code Builders That Run Open-Weight Models
- Best Open-Source LLMs
- Moonshot AI and Kimi History
- Kimi Model Results in the TSK-1 Benchmark
- How AI Data Centers Work
- AI Reasoning Models Explained
- Reduce LLM Costs
- How Do LLMs Work?
- LLM vs RAG vs AI Agent vs Agentic AI
- The History of Context Windows
- DeepSeek AI History
- What Are AI Agents?
- Best AI Agent Platforms
- Best AI App Builders
- Explore community apps · AI app builder