Introducing TSK-1Introducing TSK-1·Taskade's intelligence layer.
taskade
PricingHelpDashboard →Dashboard →
PricingLoginSign up for free →Sign up for free →
Dashboard →Dashboard →
Sign up →Sign up →
Loved by 1M+ users·Hosting 150,000+ apps·Deploying 500K+ AI agents·Running 1M+ automations·Backed by Y Combinator·Powered by TSK-1
TaskadeAppsTSK-1BuilderPricingFeaturesContact usIntegrationsMCP ServerPressAbout
ConnectProductivityVideosReviewsFAQ
LearnGenesisProjectsAI Agents
AutomationConnectorsAccount & BillingImport & ExportVideo TutorialsSearch Articles
DocsGetting StartedREST APIAction API
MCP ServersGuides & SDKModels
Community
FeaturedQuick AppsToolsDashboardsWebsites
WorkflowsProjectsFormsCreators
DownloadsAndroidiOSMacWindows
ChromeFirefoxEdge
Compare
vs Cursorvs Boltvs Lovablevs V0vs Windsurf
vs Replitvs Emergentvs Devinvs Claude Codevs ChatGPTvs Claudevs Perplexityvs GitHub Copilotvs Figma AIvs Notionvs ClickUpvs Asanavs Mondayvs Trellovs Jiravs Linearvs Todoistvs Evernotevs Obsidianvs Airtablevs Basecampvs Mirovs Slackvs Bubblevs Retoolvs Webflowvs Framervs Softrvs Glidevs FlutterFlowvs Base44vs Adalovs Durablevs Gammavs Squarespacevs WordPressvs UI Bakeryvs Zapiervs Makevs n8nvs Jaspervs Copy.aivs Writervs Rytrvs Manusvs Crewvs Lindyvs Relevance AIvs Wrikevs Smartsheetvs Monday Magicvs Codavs TickTickvs Any.dovs Thingsvs OmniFocusvs MeisterTaskvs Teamworkvs Workfrontvs Bitrix24vs Process Streetvs Toggl Planvs Motionvs Momentumvs Habiticavs Zenkitvs Google Docsvs Google Keepvs Google Tasksvs Microsoft Teamsvs Dropbox Papervs Quipvs Roam Researchvs Logseqvs Memvs WorkFlowyvs Dynalistvs XMindvs Whimsicalvs Zoomvs Remember The Milkvs Wunderlist
Taskade AIVideo GuideAI App BuilderVibe CodingAgent BuilderDashboard Builder
CRM BuilderWebsite BuilderForm BuilderWorkflow AutomationWorkflow BuilderBusiness-in-a-BoxAI for MarketingAI for Developers
AI Agents
FeaturedProject ManagementOperations IntelligenceProductivityMarketing
TranslatorContentWorkflowResearchPersonalSalesSocial MediaTo-Do ListCRMTask AutomationCoachingCreativityTask ManagementBrandingFinanceLearning and DevelopmentBusinessCommunity ManagementMeetingsAnalyticsDigital AdvertisingContent CurationKnowledge ManagementProduct DevelopmentPublic RelationsProgrammingHuman ResourcesE-CommerceEducationLegalEmailSEODeveloperVideo ProductionDesignFlowchartDataPromptNonprofitAssistantsTeamsCustomer ServiceTrainingTravel PlanningUML DiagramER DiagramMath TutorLanguage LearningCode ReviewerLogo DesignerUI WireframeFitness CoachLead EnrichmentFounder OSSales DevelopmentBookkeepingRecruitingWebsite MonitoringField ServiceLicensingAll Categories
Automations
FeaturedAI Agent AutomationAI WorkflowsLogic AutomationsTrigger Automations
Agentic Process AutomationAction AutomationsAI Models in WorkflowsAgentic AutomationMulti-Agent AutomationBusiness-in-a-BoxOperations IntelligenceInvestor OperationsEducation & LearningHealthcare & ClinicsReal EstateStripeSalesHR & People OpsField Service & DispatchRenewals & LicensesE-commerceContentMarketingEmailCustomer SupportHubSpotProject ManagementAgentic WorkflowsAppointment SchedulingCalendarReportsSlackWebsiteFormTaskWeb ScrapingWeb SearchChatGPTText to ActionYoutubeLinkedInTwitterGitHubDiscordMicrosoft TeamsWebflowIndustry News & RSS FeedsGoogle WorkspaceManufacturing & OperationsAI Agent TeamsNotion AutomationsProposalBookkeeping & ExpensesClient OnboardingGoogle SheetsGoogle DriveGoogle CalendarGoogle FormsShopifyAsanaAirtableTrelloTodoistMailchimpClickUpGoogle DocsGmailGoogle TasksJiraLinearMicrosoft OutlookTelegramCalendlyTypeformSalesforceMonday.comTwilioWhatsApp BusinessWordPressZoomHTTP and WebhooksMCP AutomationFacebook PagesRedditApolloAll Categories
Wiki
Taskade GenesisAI AgentsAutomation
ProjectsLiving DNAAutonomous Workspaces, Agents & AppsQuantum AI & Taskade Genesis QuantumFoundations: The Theory Under Modern AIPlatformAI InfrastructureIntegrationsProductivityMethodsProject ManagementAgileScrumAI ConceptsCommunityTerminologyFeatures
Templates
FeaturedChatGPTOperations IntelligenceTablePersonal
Project ManagementSalesFlowchartTask ManagementEngineeringEducationDesignTo-Do ListMarketingMind MapGantt ChartOrganizationalPlanningMeetingsTeam ManagementStrategyGamingProductionProduct ManagementStartupRemote WorkY CombinatorRoadmapCustomer ServiceLegalEmailBudgetsContentConsultingE-CommerceStandard Operating Procedure (SOP)Human ResourcesProgrammingMaintenanceCoachingSocial MediaHow-TosResearchMusicTrip PlanningCRMClient OnboardingEmployee OnboardingSOPBug TrackerRecruitment TrackerFormSales PipelineContent CalendarMarketing PlanProduct RoadmapBusiness PlanSWOT Analysis30-60-90 Day PlanInterviewNotion AlternativeKPIStrategic PlanMeeting AgendaInvoiceRisk RegisterIT Asset ManagementKanban BoardChange ManagementCommunication PlanRFPScope of WorkStatement of WorkHelpdeskKnowledge BaseCreative BriefGoal SettingExecutive SummaryGap AnalysisBooking SystemEvent ManagementPortfolio TrackerCustomer Onboarding PortalsClient PortalAgency OperationsFinance TrackingAll Categories
Generators
AI SoftwareNo-Code AI AppAI AppAI WebsiteAI Dashboard
AI FinanceAI Operations IntelligenceAI FormAI AgentAI Client Portal BuilderAI WorkspaceAI ProductivityAI To-Do ListAI WorkflowsAI EducationAI Mind MapsAI FlowchartAI Scrum Project ManagementAI Agile Project ManagementAI MarketingAI Project ManagementAI Social Media ManagementAI BloggingAI Agency WorkflowsAI ContentAI Software DevelopmentAI MeetingAI PersonasAI OutlineAI SalesAI ProgrammingAI DesignAI FreelancingAI ResumeAI Human ResourceAI SOPAI E-CommerceAI EmailAI Public RelationsAI InfluencersAI Content CreatorsAI Customer ServiceAI BusinessAI PromptsAI Tool BuilderAI SEOAI Gantt ChartAI CalendarsAI BoardAI TableAI ResearchAI LegalAI ProposalAI Video ProductionAI Health and WellnessAI WritingAI PublishingAI NonprofitAI DataAI Event PlanningAI Game DevelopmentAI Project Management AgentAI Productivity AgentAI Marketing AgentAI Personal AgentAI Business and Work AgentAI Education and Learning AgentAI Task Management AgentAI Customer Relations AgentAI Programming AgentAI SchemaAI Business PlanAI Pitch DeckAI InvoiceAI Lesson PlanAI Social Media CalendarAI API DocumentationAI Database SchemaAI Marketing PlanAI Sales Pipeline GeneratorAI Course BuilderInternal ToolsBooking SystemReal Estate CRMInventory ManagementAI CRM BuilderAI TimesheetAI DispatchAI NewsletterAI Clinic OperationsAI Directory BuilderAll Categories
Converters
AI Featured ConvertersAI PDF ConvertersAI CSV ConvertersAI Markdown ConvertersAI Prompt to App Converters
AI Data to Dashboard ConvertersAI Workflow to App ConvertersAI Idea to App ConvertersAI Flowcharts ConvertersAI Mind Map ConvertersAI Text ConvertersAI Youtube ConvertersAI Knowledge ConvertersAI Spreadsheet ConvertersAI Email ConvertersAI Web Page ConvertersAI Video ConvertersAI Coding ConvertersAI Task ConvertersAI Kanban Board ConvertersAI Notes ConvertersAI Education ConvertersAI Language TranslatorsAI Business → Backend App ConvertersAI File → App ConvertersAI SOP → Workflow App ConvertersAI Portal → App ConvertersAI Form → App ConvertersAI Schedule → Booking App ConvertersAI Metrics → Dashboard ConvertersAI Game → Playable App ConvertersAI Catalog → Directory App ConvertersAI Creative → Studio App ConvertersAI Agent → Agent App ConvertersAI Audio ConvertersAI DOCX ConvertersAI EPUB ConvertersAI Image ConvertersAI Resume & Career ConvertersAI Presentation ConvertersAI PDF to Spreadsheet ConvertersAI PDF to Database ConvertersAI PDF to Quiz ConvertersAI Image to Notes ConvertersAI Audio to Notes ConvertersAI Email to Tasks ConvertersAI CSV to Dashboard ConvertersAI YouTube to Flashcards ConvertersURL to NotesVideo → SummaryAI Receipts to Expense Tracker ConvertersAI Docs to Knowledge Base ConvertersAI Form to Client Portal ConvertersSpreadsheet to CRMAll Categories
Prompts
Client PortalsDocument IntakeField Service
Operations IntelligenceCRMAdvertisingDesignInvoicing and PaymentsSocial MediaQuotes and EstimatesCalculatorsCodingBooking and SchedulingConsultingCustomer SupportComplianceTime TrackingRetail OperationsSaaS and SubscriptionsInsuranceGovernance and OversightNonprofitPatient IntakeBlog WritingBrandingPersonal FinanceHuman ResourcesPublic RelationsTeam CollaborationProduct ManagementSupportAgencyReal EstateMarketingResearchSalesCopywritingContentProject ManagementWebsite CreationStrategyE-commerceEngineeringSEOEducationEmail MarketingUX/UIProductivityInfluencer MarketingAnalyticsEntrepreneurshipLegalVibe CodingRecruitingAll Categories
Blog
Introducing Taskade TSK-1: The System Kernel Behind Every App (2026)The TSK-1 Methodology: How We Benchmark AI Models by Building Real Apps (2026)Paste Your Website, Clone an App Kit, Launch It Live (September 2026)
Open Source Temporal Parser: Parse ISO 8601, RFC 3339, and IXDTF in TypeScript (2026)Best AI Model for Building Apps in 2026: One Prompt, Nine Models, Real Apps Side by SideChat-Native App Builders in 2026: What You Actually Own When the Chat EndsGenerate the Art. Preview the Agent. Put It on Your Domain (2026)Agentic Automation Explained: Agent vs AI Step (2026)The Scaffolding Tax: Why Less Prompt Beats More (2026)History of Mind Mapping: From Porphyry to Buzan to AI (2026)The Bitter Lesson Explained: Richard Sutton's 26 Words (2026)Self-Replicating Code: Quines, von Neumann, and the Programs That Copy Themselves (2026)Markov Chains Explained: The Memoryless Math Behind Google, Monte Carlo, and ChatGPT (2026)Add Client Logins. Connect Your Domain. Ship a Real Product in 2026Track Customer Health. Catch Churn Early. Keep the Accounts You Won (2026)Compression Is Intelligence: What Cross-Entropy Really Measures (2026)Automate License Renewals. Track Every Key. Own Your Software Spend (2026)Track Hours. Bill Clients. Get Paid. (Clone a Working Time Tracker in 2026)Claude Shannon: The History of Information Theory and the Man Who Invented the Bit (2026)Run Your Whole Business in One App with Taskade Genesis (June 2026)
AIAutomationProductivityProject ManagementRemote WorkStartupsKnowledge ManagementCollaborative WorkUpdates
Changelog
Numbered Agent Citations & Shareable Chat Links (Sep 15, 2026)Sturdier Builds & Clearer Automation Runs (Sep 14, 2026)App Users Stay Signed In & App Kit Sharing (Sep 11, 2026)
Faster App Thumbnails & Sturdier App Builds (Sep 11, 2026)Trusted App Restores & Remembered AI Models (Sep 10, 2026)Embedded Agent Controls & Safer Project Edits (Sep 9, 2026)Email Abuse Blocking Hotfix (Sep 8, 2026)
Wiki
Taskade GenesisAI AgentsAutomation
ProjectsLiving DNAAutonomous Workspaces, Agents & AppsQuantum AI & Taskade Genesis QuantumFoundations: The Theory Under Modern AIPlatformAI InfrastructureIntegrationsProductivityMethodsProject ManagementAgileScrumAI ConceptsCommunityTerminologyFeatures
Prompts
Client PortalsDocument IntakeField Service
Operations IntelligenceCRMAdvertisingDesignInvoicing and PaymentsSocial MediaQuotes and EstimatesCalculatorsCodingBooking and SchedulingConsultingCustomer SupportComplianceTime TrackingRetail OperationsSaaS and SubscriptionsInsuranceGovernance and OversightNonprofitPatient IntakeBlog WritingBrandingPersonal FinanceHuman ResourcesPublic RelationsTeam CollaborationProduct ManagementSupportAgencyReal EstateMarketingResearchSalesCopywritingContentProject ManagementWebsite CreationStrategyE-commerceEngineeringSEOEducationEmail MarketingUX/UIProductivityInfluencer MarketingAnalyticsEntrepreneurshipLegalVibe CodingRecruitingAll Categories
© 2026 Taskade
PrivacyTermsSecurity
Made withTaskade AIforBuilders
BlogAIAI Reasoning Models…

AI Reasoning Models Explained: Chain-of-Thought, Test-Time Compute, and When to Pay for Thinking (2026)

Reasoning models spend extra compute thinking before they answer. Here is how chain-of-thought, test-time compute, and RL training work, with a decision framework for when paying for thinking is worth it.

AI reasoning models explained: chain-of-thought and test-time compute in 2026
June 18, 202614 min readTaskade TeamAI·#ai-models#reasoning#chain-of-thought
On this page (10)
What Is an AI Reasoning Model?Reasoning Model vs. Standard LLM: What Actually ChangedThe Three Ideas Behind ReasoningHow a Reasoning Model Thinks, Step by StepTest-Time Compute Scaling: Why Thinking Longer WorksWhen to Use a Reasoning Model vs. a Standard ModelThe 2026 Reasoning-Model LineupHow to Control Thinking Depth: and Why Routing Is the Real AnswerReasoning Inside Taskade: Thinking Without the ConfigurationFrequently Asked Questions About AI Reasoning Models

In September 2024, OpenAI previewed a model that did something strange: it paused, thought, and only then answered. On AIME 2024, a hard high-school math contest, the previous flagship (GPT-4o) scored about 12%. The thinking model scored about 74% pass@1. Nothing about the training data changed that much. What changed was when the compute was spent, at answer time, not just at training time.

That shift created a new category: the reasoning model. By 2026 it's everywhere, and it raises a practical question every builder now faces, when is it worth paying for a model to think, and when are you just burning money and latency on a task a fast model would have nailed? This is the vendor-neutral guide.

TL;DR: A reasoning model spends extra inference compute, test-time compute, generating intermediate "thinking tokens" before it answers, which makes it far stronger on math, code, and planning but slower and pricier. Use it for hard multi-step problems; use a standard model for lookups and chat. The real answer isn't one model. It's matching the model class to the job. Taskade offers 15+ frontier models, and TSK-1 Auto handles the default.


What Is an AI Reasoning Model?

An AI reasoning model is a large language model trained to spend extra computation thinking before it answers. Where a standard model predicts its response in essentially one pass, a reasoning model first generates a chain of internal reasoning, exploring, checking, and sometimes backtracking, and only then commits to a final answer. The psychologist's shorthand is useful here: standard models are System 1 (fast, intuitive), reasoning models add System 2 (slow, deliberate).

Prompt Standard LLMsingle forward pass Answerfast, cheap Reasoning modelgenerate thinking tokens explore · check ·backtrack · verify Answerslower, costlier, stronger

The mechanism is grounded in three ideas the field assembled over four years, chain-of-thought, test-time compute, and reinforcement learning. Understand those three and you understand every reasoning model on the market. (For the layer below this, how a model turns tokens into predictions at all, see how large language models work.)


Reasoning Model vs. Standard LLM: What Actually Changed

The difference is when and how much the model computes, not what it fundamentally is. A standard LLM and a reasoning model are both transformers trained on text. The reasoning model is additionally trained to produce a long internal reasoning trace and is given the inference budget to do so. That single change cascades into every practical trade-off you care about.

Dimension Standard LLM Reasoning model
Inference pattern one forward pass, next-token generates reasoning tokens, then answers
Latency sub-second to seconds 5 to 60+ seconds
Cost per answer lower higher (you pay for thinking tokens)
Best tasks lookup, summarize, chat, classify math, code, multi-step planning, agents
Weakness struggles on multi-step logic over-thinks simple tasks; slow; pricey

The headline that made everyone pay attention: on AIME 2024, GPT-4o scored roughly 12%, while OpenAI's o1 scored about 74% pass@1 (higher still with consensus voting) and o1-mini about 70%. The model class, not a bigger training run, closed most of that gap.


The Three Ideas Behind Reasoning

Reasoning models stand on three building blocks, each solving a limitation of the last. They arrived in sequence, and the sequence is the clearest way to understand the category.

Idea Year / source What it added Key result
Chain-of-thought 2022, Wei et al. reason in steps before answering emergent at ~100B+ params; inference-time only
Test-time compute scaling 2024, Snell et al. spend more compute at answer time a smaller model can beat one up to 14x larger
RL for reasoning (GRPO) 2025, DeepSeek-R1 train reasoning via rewards, not prompts AIME pass@1 15.6% → 71.0% through pure RL

Chain-of-thought (Wei et al., Google, January 2022) showed that simply prompting a large model to "think step by step" dramatically improved multi-step accuracy. But only above ~100B parameters, and only as an inference-time trick, not a change to the weights.

Test-time compute (Snell et al., 2024) reframed CoT as a scaling axis: spend more compute when answering, and accuracy rises. Their compute-optimal finding is the one to remember, a smaller model, given the right thinking budget, can outperform a model up to 14x larger at matched compute, and the best strategy depends on problem difficulty.

Reinforcement learning turned the prompt trick into a trained behavior. DeepSeek-R1 (January 2025, later published in Nature) used Group Relative Policy Optimization (GRPO), which drops the separate critic model and estimates the baseline from a group of sampled answers, to reward correct, verifiable answers. Through pure RL, DeepSeek-R1-Zero's AIME 2024 pass@1 climbed from 15.6% to 71.0% (and 86.7% with majority voting). Crucially, DeepSeek released R1 as open weights with distilled Qwen and Llama variants, putting reasoning in reach of anyone.


How a Reasoning Model Thinks, Step by Step

A reasoning model runs an internal loop before it speaks: it drafts reasoning, checks it against the goal, revises, and only emits the visible answer once it's satisfied (or hits its budget). Those intermediate steps are the thinking tokens, usually hidden from you, always billed to you.

Hard question Draft reasoning (thinking tokens) Propose a step Verify / backtrack if wrong Final answer (reasoning hidden) Loop until confident or budget hit User Reasoning model Hidden scratchpad Self-check

This is why a reasoning answer can take 5 to 60+ seconds: the model is doing real work you don't see. It's also why "over-thinking" is a real cost, point a reasoning model at "what's the capital of France" and you pay for a paragraph of deliberation to produce one word.
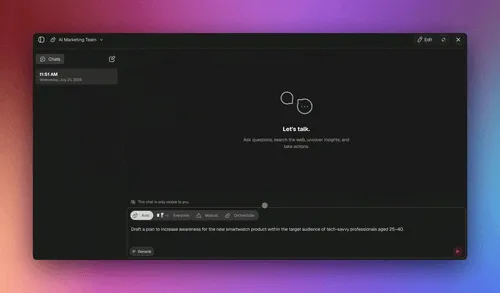
Orchestration mode for AI agents in Taskade


Test-Time Compute Scaling: Why Thinking Longer Works

Accuracy rises with thinking compute. But with diminishing returns. The first chunk of reasoning buys the biggest jump; past a point, more thinking adds latency and cost for little gain. Visualizing the curve is the fastest way to build intuition for how much thinking to pay for.

none low medium high max 0 20 40 60 80 100 Thinking compute (log scale) Accuracy % Accuracy vs. test-time compute (illustrative)

The shape is the point: the climb from "none" to "medium" is steep; the climb from "high" to "max" is nearly flat. Snell's compute-optimal result formalizes this. There's a right amount of thinking for a given problem difficulty, and spending past it is waste. That single insight is the foundation of the decision framework below.


When to Use a Reasoning Model vs. a Standard Model

Use a reasoning model when a wrong intermediate step ruins the answer; use a standard model when the task is a lookup, a rewrite, or high-volume. The dividing line is whether the problem is multi-step and verifiable. Math, code, and agent planning qualify. Summarizing an email does not.

No Yes No Yes Yes No Is the task multi-stepmath, code, or planning? Standard modelfast + cheap Does a wrong stepcompound or break things? High-volume orlatency-sensitive? Route: reasoning onlyfor the hard subset Reasoning modelworth the thinking cost
When to pay for thinking Use a reasoning model? Why
Multi-step math / proofs Yes each step must be correct
Code generation + debugging Yes logic errors compound
Agent planning / tool sequencing Yes a bad plan wastes every tool call
Lookup / Q&A from context No a fast model is enough
Summarize / rewrite No no multi-step logic
High-volume classification No cost and latency dominate

The 2026 Reasoning-Model Lineup

By 2026, every major lab ships a reasoning model, and they expose "thinking" in different ways. Naming them is education, not endorsement, the point is that the category is now standard, and each option trades off openness, cost, and control differently.

Model family How thinking is exposed Open or closed Standout strength
OpenAI o-series / GPT-5 thinking hidden reasoning tokens; real-time router closed auto-routing fast vs. deep
DeepSeek-R1 full reasoning trace; RL-trained open weights accessible, distillable
Claude extended / adaptive thinking budget_tokens / effort parameter closed tunable thinking budget
Gemini 2.5 thinking thinkingBudget; Deep Think mode closed thinking with 1M+ context

A few verified specifics worth knowing: OpenAI's GPT-5 (August 2025) is a unified system with a fast model, a deeper "GPT-5 thinking" model, and a router that picks between them; OpenAI reports it matches its prior reasoning model with 50–80% fewer output tokens. Anthropic's Claude exposes extended thinking via a budget_tokens parameter (minimum 1,024) and interleaved thinking across tool calls. Google's Gemini 2.5 models carry a configurable thinkingBudget. The throughline: thinking is becoming a dial, not a fixed mode.


How to Control Thinking Depth: and Why Routing Is the Real Answer

The single biggest cost mistake in 2026 is running every request through a reasoning model. The fix has two parts: cap thinking depth where the platform allows it (budgets, effort levels), and, more importantly, route by task difficulty so only the hard requests pay for deliberation.

simple / high-volume hard / multi-step Incoming task Router assessesdifficulty + intent Fast standard model Deep reasoning model Response

OpenAI built this routing logic into GPT-5. The deeper conclusion from Snell's compute-optimal finding is that routing is correct in principle: since the best amount of thinking depends on difficulty, a system that matches model class to task beats committing to one model for everything.

ROUTING, AS A RULE OF THUMB
  ┌───────────────────────────┬──────────────────────────┐
  │ "What's our refund policy" │ → fast model    (~$, ~1s) │
  │ "Summarize this thread"    │ → fast model    (~$, ~2s) │
  │ "Debug this failing test"  │ → reasoning     ($$, ~20s)│
  │ "Plan a 6-step migration"  │ → reasoning     ($$, ~30s)│
  └───────────────────────────┴──────────────────────────┘
  Same workspace, many models. TSK-1 Auto handles the default.

This is exactly how reasoning fits into the AI agent stack: the reasoning layer is the model and the routing logic around it, and agentic workflows lean on reasoning for the planning step where a bad decision wastes every downstream tool call.


Reasoning Inside Taskade: Thinking Without the Configuration

Taskade gives you the conclusion without the wiring. Agents and automations get access to 15+ frontier models from OpenAI, Anthropic, Google, and open-weight providers, and TSK-1 Auto handles the default, so you can reach for extended reasoning when a job needs deep problem-solving and a fast model when it doesn't.
Build with Taskade Genesis, where TSK-1 Auto handles the default model

That means a custom agent handling your support inbox can run on a fast model while a second agent takes the gnarly edge case on a reasoning model, in the same workspace, and TSK-1 Auto handles the default on anything you do not pin. It's the same philosophy as Taskade EVE, the meta-agent that builds Taskade Genesis apps: describe the goal, and the workspace assembles the agents, tools, and memory around it. Reasoning becomes a property of the workspace, not a configuration chore, and it pairs with persistent agent memory and 100+ integrations so the thinking happens over your real data and acts on real systems.


Frequently Asked Questions About AI Reasoning Models

What is an AI reasoning model in simple terms?

It's an LLM trained to think before it answers, generating intermediate reasoning steps (often hidden) to work through hard problems, then returning a final answer. That extra inference-time work, called test-time compute, is why reasoning models score far higher on math and code but cost more and respond slower than standard models.

How is a reasoning model different from a standard LLM?

A standard LLM answers in roughly one forward pass; a reasoning model first generates reasoning tokens, checks its work, and then answers. The result is stronger multi-step performance but 5 to 60+ second latency and higher cost, since you pay for the thinking tokens. For lookups and chat, a standard model is the better pick.

What is chain-of-thought reasoning?

Chain-of-thought is getting a model to reason step by step before answering. Introduced by Wei et al. at Google in January 2022 (arXiv:2201.11903), it's an emergent ability that only helps at roughly 100B+ parameters and is purely an inference-time technique. Modern reasoning models train this behavior in via reinforcement learning rather than relying on a prompt.

What does test-time compute mean?

It's the computation a model spends at inference, after training, to think before answering, a third scaling axis beyond more parameters and more data. Snell et al. (2024) showed compute-optimal test-time scaling can let a smaller model beat one up to 14x larger at matched compute, with the best strategy depending on problem difficulty.

What are thinking tokens and do I pay for them?

Thinking tokens are the internal reasoning generated before the visible answer. They're usually hidden but billed as output tokens, which is why reasoning costs more. Most models let you cap the budget, Claude via budget_tokens (minimum 1,024), Gemini via thinkingBudget. So you control how much the model spends thinking.

When should I use a reasoning model instead of a standard model?

Use reasoning for multi-step math, code, complex planning, and agent workflows where a wrong step compounds. Use a standard model for lookups, summaries, classification, chat, and high-volume work where speed and cost win. For most teams the right move is routing each task to the right class automatically.

Is o1 or DeepSeek-R1 better for reasoning?

Both are strong with different trade-offs. o1-preview (September 2024) pioneered hidden reasoning tokens; the o1 series scored ~74% pass@1 on AIME 2024 versus ~12% for GPT-4o. DeepSeek-R1 (January 2025, published in Nature) reached ~79.8% pass@1 on AIME 2024 and shipped as open weights with distilled smaller variants. Choose based on whether you need open weights, cost, and latency.

Are reasoning models slower and more expensive?

Yes. They generate reasoning tokens before answering, so they respond in 5 to 60+ seconds and bill those tokens, making each answer pricier. The payoff is much higher accuracy on hard tasks. The waste is over-thinking simple tasks, which is why controlling depth and routing by difficulty matter.

Can a smaller reasoning model beat a bigger standard model?

Yes, on the right tasks. Snell et al. (2024) found compute-optimal test-time scaling can let a smaller model outperform one up to 14x larger at matched compute, and DeepSeek-R1's distilled variants reason well at small sizes. How a model uses inference compute can matter as much as raw size.

Do I have to choose one reasoning model, or can I route between them?

You can route. GPT-5 (August 2025) ships a real-time router between a fast and a thinking model. Platforms can offer the same range: Taskade gives you 15+ frontier models, and TSK-1 Auto handles the default, so choosing a model is optional.

How does reinforcement learning train a reasoning model?

RL rewards a model for reaching correct, verifiable answers, which pushes it to develop useful reasoning. DeepSeek-R1 used GRPO, which drops the critic model and estimates the baseline from a group of sampled answers to cut cost. Through pure RL, DeepSeek-R1-Zero's AIME 2024 pass@1 rose from 15.6% to 71.0%. The places that reward happens are called RL environments, and they are where a large share of AI progress now comes from.

Does Taskade support reasoning models?

Yes. Taskade gives agents 15+ frontier models from OpenAI, Anthropic, Google, and open-weight providers, including reasoning models, and TSK-1 Auto handles the default. You can reach for extended reasoning on hard problems and a fast model otherwise, with no model configuration. Taskade starts free, with paid plans from $10/month billed annually.


The reasoning-model era didn't make models bigger. It made them think. The skill it asks of you isn't picking the smartest model; it's knowing which problems deserve deliberation and which just need a fast, correct answer. Master that and you stop overpaying for thinking you don't need, and start spending it exactly where it changes the outcome.

That's the reasoning layer of the stack: Memory feeds it context, Intelligence does the thinking, Execution acts on the result, on a loop. ▲ ■ ●

Want reasoning built into your work without the configuration? Start free with Taskade Genesis, let TSK-1 Auto handle the default for your AI agents, and wire it into automations.

0%

On this page

What Is an AI Reasoning Model?Reasoning Model vs. Standard LLM: What Actually ChangedThe Three Ideas Behind ReasoningHow a Reasoning Model Thinks, Step by StepTest-Time Compute Scaling: Why Thinking Longer WorksWhen to Use a Reasoning Model vs. a Standard ModelThe 2026 Reasoning-Model LineupHow to Control Thinking Depth: and Why Routing Is the Real AnswerReasoning Inside Taskade: Thinking Without the ConfigurationFrequently Asked Questions About AI Reasoning Models

Related Articles

The TSK-1 methodology: the dated benchmark updates log on the Taskade hub, one entry per results day from July 30 to August 20, 2026
September 15, 2026AI

The TSK-1 Methodology: How We Benchmark AI Models by Building Real Apps (2026)

The full TSK-1 method: frozen requests, one to three builds per model per test, a customer-style check of every saved fi...

Grandfather clock with a date dial — a visual for an open-source temporal parser that lexes ISO 8601, RFC 3339, and IXDTF strings. Photo: Wikimedia Commons / LoKiLeCh / CC BY-SA 3.0
September 10, 2026AI

Open Source Temporal Parser: Parse ISO 8601, RFC 3339, and IXDTF in TypeScript (2026)

Date.parse guesses and Temporal ships no parser. @taskade/temporal-parser is a zero-dependency TypeScript lexer for ISO ...

Best AI model for building apps in 2026: the TSK-1 matrix grading Claude, GPT, DeepSeek, Kimi, GLM, Grok, Qwen, Gemini and MiniMax on Interface, Task, Memory and Adapt
September 8, 2026AI

Best AI Model for Building Apps in 2026: One Prompt, Nine Models, Real Apps Side by Side

We gave nine AI models the same app request inside Taskade Genesis and graded the app each one shipped. No model won eve...

A live app built from a prompt, running with its own database, agents, and automations
September 1, 2026AI

Chat-Native App Builders in 2026: What You Actually Own When the Chat Ends

Claude, ChatGPT, and Gemini can all build an app inside the chat. The question nobody answers is what survives when you ...

Previewing and customizing a branded AI agent in Taskade before publishing it as a public page, a custom domain, or a website widget
August 31, 2026AI

Generate the Art. Preview the Agent. Put It on Your Domain (2026)

Ship an AI agent that looks like your company: generate its art in the workspace, preview it the way a visitor sees it, ...

An AI agent with its own tools running inside a Taskade automation
August 30, 2026AI

Agentic Automation Explained: Agent vs AI Step (2026)

Agentic automation runs a named agent with memory and tools inside a workflow. Here is the five-point test that separate...

View All Articles