TL;DR: Same tests, different wins. GPT-5.6 Luna is the most faithful model we have tested: all 32 of a customer's questions word for word (Aug 3, 2026) and the only working scoring grid that saves scores back into your workspace (Aug 7, 2026). GLM-5.2 is the model that said no: the only one to refuse a login screen nobody asked for (Jul 30, 2026), in the very test where GPT-5.6 Sol added one. On Aug 25, 2026 all four met again: Terra led, Luna missed on both apps, and Sol added its third unasked-for sign-in screen. Route by task inside Taskade Genesis rather than standardizing on one.
What TSK-1 Found
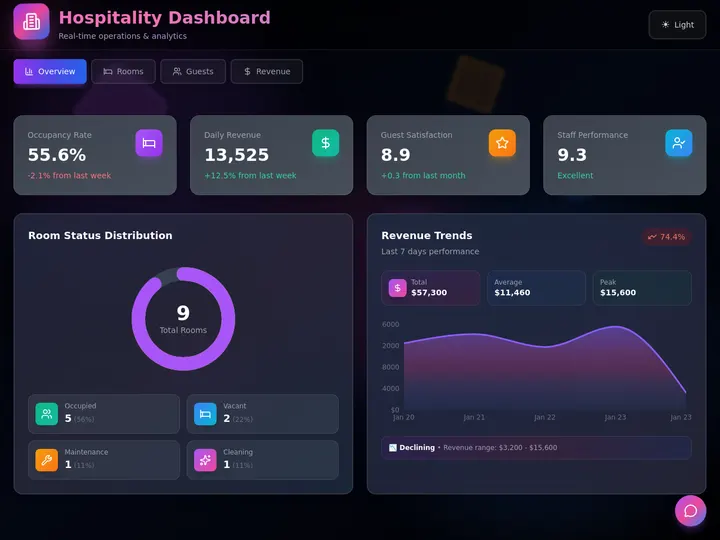
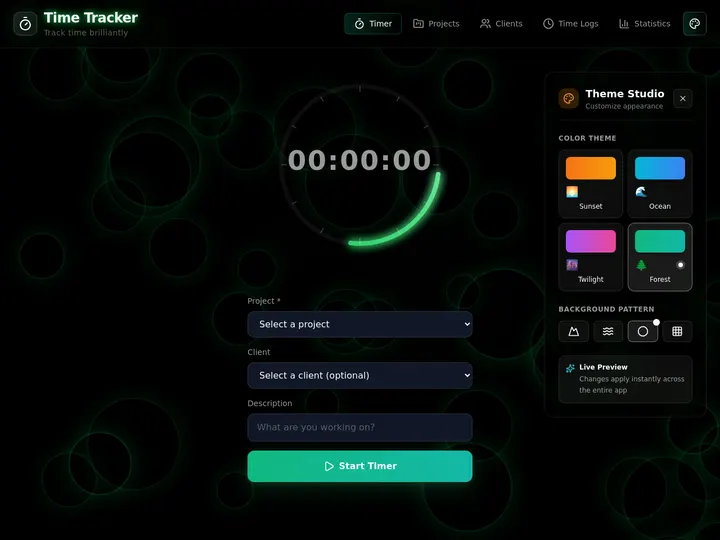
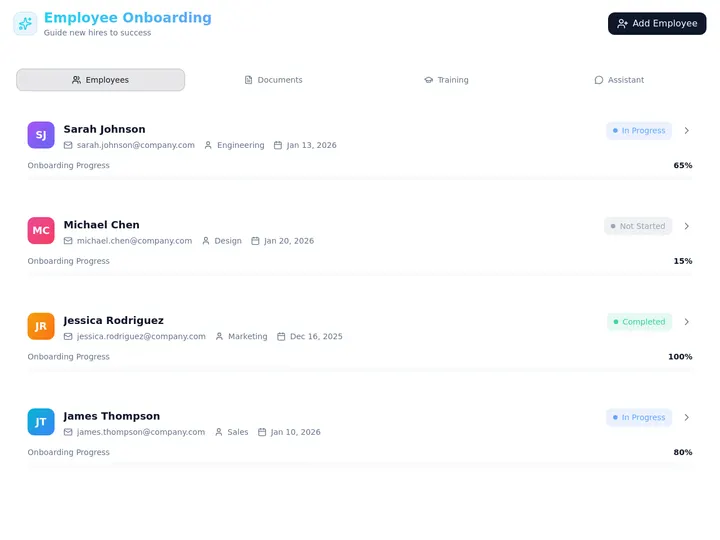
We ran both families in the same tests, including one on Aug 25, 2026 where GLM-5.2, Luna, Terra, and Sol all built the same two apps. The findings split on judgment versus precision. GPT-5.6 Luna is the most faithful model we have tested: all 32 questions of a real customer's client sign-up form word for word on Aug 3, 2026, and again through August. GLM-5.2 was the only model to push back rather than quietly add something: it considered a sign-in screen, decided the brief had not asked for one, and offered it as a suggestion instead (Jul 30, 2026). Its data saving arrived on Aug 1, 2026.
- GPT: Aug 3, 2026, Luna carried all 32 questions word for word. Aug 7, 2026, Luna built the only working scoring grid, and Terra passed all five checks in a single run at 8 minutes 26 seconds. Aug 25, 2026, in the same test as GLM, Terra built the best overall match tracker and the best client sign-up build, Luna's match tracker crashed on the first real entry and its sign-up form rejected the first submission, and Sol added a sign-in gate for the third time in three tests.
- GLM: Jul 30, 2026, refused the login screen nobody asked for. Aug 1, 2026, its app saved real data for the first time. Aug 25, 2026, in that same test, its match tracker was complete and working, but its sample matches carried no result, so the dashboard showed a 0% win rate until a real match was logged. Aug 29, 2026, the newer GLM-5.3 built four pages but did not finish inside the time limit, produced no app on the 32-question client sign-up form, and landed both follow-up edits with no failed build actions.
See the full evidence at /tsk/glm, /tsk/gpt, and the TSK-1 hub.
GLM-5.2 vs GPT-5.6 Luna
Luna is the precision pick, and GLM is the judgment pick. The gap between them is about what each one does when a brief is silent. Give Luna a long, detailed brief and it comes back with the brief intact. On Aug 3, 2026 it reproduced all 32 questions of a real customer's client sign-up form word for word, and it was the only model to get all four of its builds word for word across more than one test.
Luna's most distinctive result is about your data. On Aug 7, 2026 it built a working scoring grid, 33 rows by 5 ratings, and saved every score straight back into the workspace. No other model attempted that. An app that keeps its own scores is one you can run a business on.
Luna also has an honest miss, from the test where it met GLM-5.2 directly. On Aug 25, 2026 its match tracker crashed on the first real entry and its sign-up form rejected the first submission. Its later tests finished cleanly, and on Aug 27, 2026 it was the value pick on every app in a five-model test of identical prompts.
GLM-5.2's story starts one step earlier. On Jul 30, 2026 the brief left room for a sign-in screen it never asked for. GLM weighed it up, decided the brief had not called for one, and offered "Add Login" as a suggestion instead. It was the only model in that test to push back rather than quietly add something. Then on Aug 1, 2026 its app saved real data for the first time, with a small styling issue as the one thing still open. On Aug 25, 2026, in the same test as Luna, its match tracker was complete and working. Its sample matches carried no result, so the dashboard showed a 0% win rate until a real match was logged. The newer GLM-5.3, tested on Aug 29, 2026, built four pages but did not finish inside the time limit, produced no app on the 32-question form, and landed both follow-up edits with no failed build actions.
So the two split cleanly. When the brief is precise and long, Luna keeps every word of it and saves the results. When the brief is loose, GLM is the one that asks before it builds more than you wanted.
GLM-5.2 vs GPT-5.6 Terra and Sol
Terra is the speed pick, and Sol is the lesson that beautiful is not the same as right. Terra is the fastest model in nearly every test it enters. On Aug 7, 2026 it finished in 8 minutes 26 seconds, and it was the first model to pass all five checks in a single run: it built the app, took a form submission, put every answer in the right field, ran the automation, and answered questions about the data. On Aug 25, 2026, in the same test as GLM-5.2, Terra built the best overall match tracker and the best client sign-up build of the test: form to saved score worked on the first try.
Terra also carries an honest caveat. For three tests none of its four builds carried the customer's questions word for word. A change of setting turned that around on Aug 8, 2026, when both of its builds carried all 32 questions word for word. Its premium setting is a different story: on the client sign-up form it was the worst value we have measured, far more expensive than Luna, and it delivered less, a single page rewritten 19 times.
Sol is the direct counterpart to GLM's best finding. In the same Jul 30, 2026 test where GLM declined the sign-in screen, Sol added one and never mentioned it. On Aug 1, 2026 it did the same thing again. On Aug 25, 2026 it added a sign-in gate to the match tracker, the third time in three tests. That repeat is why we now score a build that answers a different brief than the one given. We open every app and use it, which is how the extra screen was caught. The lock on the front door was still not in the brief.
Put GLM beside Terra and Sol, and the routing rule writes itself. Terra when the brief is precise and the clock matters. GLM when the brief is loose and quietly added scope is the risk.
Choose GLM If…
A comparison that never concedes anything is not worth reading. GLM is the better pick in several common cases.
- The request is loose and scope creep is a real risk. GLM is the model that asked before it added a login screen nobody wanted (Jul 30, 2026). No GPT-5.6 size has matched that finding, and Sol did the opposite three times in three tests.
- You want the weights. GLM-5.2's published weights are MIT, so you can inspect the model, run it inside your own network or region, and fine-tune it on your own data. GPT-5.6 offers none of those, by design.
- You want one rate, not a ladder. Zhipu publishes a single price for GLM-5.2, with a cached-input discount, and no separate long-context rate.
- Long-horizon engineering is the job. Zhipu positions GLM-5.2 for exactly that and publishes its own coding scores. Treat those as vendor claims. On our side, GLM's graded strengths are behavioral.
Choose GPT If…
- The brief is long and every word matters. Luna reproduced all 32 questions of a customer's form word for word on Aug 3, 2026, and kept doing it through August. It is the most faithful model we have tested.
- Scores and answers have to land in your workspace. Luna is the only model that builds a working scoring grid and saves every score back where your team can use it (Aug 7, 2026).
- Speed matters and the brief is precise. Terra is the fastest model in nearly every test it enters, the first to pass all five checks in one run (Aug 7, 2026), and it built the best match tracker and sign-up build of the Aug 25, 2026 test.
- You need images as input. GPT-5.6 accepts text and image input on all three sizes. GLM-5.2 is text in, text out, with vision living in the separate GLM-V line.
- You want a price ladder. Luna at $0.20 in and $1.20 out is one of the cheapest frontier rate cards published, and Terra and Sol sit above it, so you can pay for exactly the size a step needs.
The Taskade Angle: Route, Don't Standardize
Most comparison pages end with "pick one". The evidence for these two families points the other way: one owns precision and speed, the other owns doing the right thing with a loose request. Serious teams run both and route between them.
Taskade routes across frontier models from top AI labs inside one workspace, with the AI allowance included in the subscription rather than a separate API account per lab. Paid plans start at Pro $10/mo billed annually, with Business $25, Max $100 and Enterprise $250 per month billed annually. You set the model per agent or per automation step, so a detailed form build on Luna, a fast pass on Terra, and a step where the request is open to interpretation on GLM-5.2 can each get the model that leads there.
Four patterns that hold up:
- Precision model builds, judgment model guards. A long, detailed brief on Luna, with GLM on the steps where quietly added scope is the risk.
- Fast model iterates, faithful model finishes. Quick passes on Terra, then a final build on Luna so every word of the brief comes through.
- Every step lands in the same project graph. Whichever model runs a step, the result becomes shared workspace memory, so the next agent inherits context instead of re-deriving it.
- Scheduled automations read from the same place. Model choice becomes a per-step setting, not a platform decision.
Frequently Asked Questions
Which is better, GLM or GPT?
They win on different measures, and both findings come from the same tests. GPT-5.6 Luna is the most faithful model we have tested: it reproduced all 32 questions of a real customer's client sign-up form word for word (Aug 3, 2026) and it is the only model that builds a working scoring grid and saves the scores back into your workspace (Aug 7, 2026). GLM-5.2 is the model that said no: it was the only model to decline a sign-in screen the brief never asked for, and to offer it as a suggestion instead (Jul 30, 2026). Pick GPT for precision and speed. Pick GLM for judgment when the request is loose. Route both and you get both.
What happened when they met on Jul 30, 2026?
Both were in the same test, and the brief never asked for a login screen. GPT-5.6 Sol added a sign-in screen anyway and did not say so. GLM-5.2 thought about the same screen, decided the brief had not asked for one, and offered "Add Login" as a suggestion instead. It was the only model in that test to push back rather than quietly add work. Sol repeated the unasked-for sign-in screen on Aug 1, 2026 and again on Aug 25, 2026, three times in three tests, which is why that finding now shapes how we score a build that answers a different brief than the one given.
Which GPT-5.6 size builds the best apps?
Luna sticks to the brief best. It reproduced a customer's wording word for word again and again through August, and it built a working scoring grid no other model attempted (Aug 7, 2026). Terra is the fastest model in nearly every test it enters, the first to pass every check in a single run (Aug 7, 2026), and the builder of the best match tracker and best client sign-up build of the Aug 25, 2026 test. Sol is the cautionary one: it added a sign-in screen nobody asked for, three times in three tests, and never mentioned it. For most app builds, start with Luna.
Is GLM open source?
GLM-5.2 is open-weight. Zhipu publishes the weights on Hugging Face under the MIT license, with no revenue threshold and no regional restriction, and also runs a managed API with a published rate card on z.ai. So you can host it yourself, call the API, or move between the two without a license change. GPT-5.6 weights are never released. OpenAI sells access through its API and its consumer products only. Both families are available in Taskade alongside frontier models from top AI labs.
How much do they cost?
On published rates as of September 2026, GLM-5.2 is $1.4 per million input tokens and $4.4 per million output, with cached input at $0.26. GPT-5.6 spans a wide range. Luna is $0.20 in and $1.20 out, Terra is $2 in and $12 out, and Sol is $4 in and $20 out. Sol's rate is promotional through Nov 21, 2026. Luna and Terra are not promotional. Cached input is one tenth of the input price on every GPT-5.6 size, and above 272K input tokens OpenAI bills input at 2x and output at 1.5x. Re-verify both rate cards at the source before you commit, because prices move.
What are the context windows?
Both reach a million tokens. GLM-5.2 lists a 1M-token context with a maximum output of 128K tokens. GPT-5.6 Luna, Terra, and Sol each list a 1,050,000-token context window with 128,000 maximum output tokens. Context length is not the deciding factor between these two families. The difference that matters more in practice is the OpenAI long-context rate: above 272K input tokens, input bills 2x and output 1.5x, while GLM publishes one rate for the whole window.
Is faster always better?
Not by itself. GPT-5.6 Terra is the fastest model we test, finishing one build in 8 minutes and 26 seconds and passing all five checks in a single run (Aug 7, 2026). But speed only counts if the app matches the brief. For three tests none of its four builds carried the customer's questions word for word. A change of setting brought it back to all 32 on Aug 8, 2026. Its premium setting was also the worst value we have measured on the sign-up form, rewriting a single page 19 times. Speed is a strength when the brief is precise. It is not a substitute for reading the brief.
Does GLM save real data?
Yes, since Aug 1, 2026. In that test GLM-5.2's app saved real data for the first time, with a small styling issue as the one thing still open. On Aug 25, 2026 its match tracker was complete and working, but its sample matches carried no result, so the dashboard showed a 0% win rate until a real match was logged. Before that, on Jul 30, 2026, its standout was judgment: it was the only model to decline the unasked-for sign-in screen. GPT-5.6 Luna goes a step further on data. It is the only model that builds a working scoring grid and saves every score straight back into the workspace (Aug 7, 2026).
Which one should I use for an AI agent?
Match the model to the step. Reach for GPT-5.6 Luna when the step has a detailed brief that must come through exactly, or when scores and answers need to land in your workspace. Reach for Terra when speed matters and the brief is precise. Reach for GLM-5.2 when the agent works from a loose request and you want it to ask before it quietly adds more. In Taskade, different agents can take different models, all sharing the same workspace memory, so a precise step and an open-ended step do not have to share a model.
Can I use GLM and GPT together inside Taskade?
Yes. Taskade routes across frontier models from top AI labs inside one workspace, with the AI allowance included in the subscription rather than a separate API account per lab. You set the model per agent or per automation step. A detailed form build can run on GPT-5.6 Luna, a fast pass on Terra, and a step where the request is open to interpretation on GLM-5.2. Leave a step on TSK-1 Auto and it adapts the depth instead: fast when the step is quick, deeper reasoning when it is not.
Final Word: Judgment vs Precision
GLM-5.2 is the judgment pick, the model that refused work nobody asked for, now saving real data with a small styling issue as its only open item. GPT-5.6 is the precision-and-speed pick: Luna keeps a customer's brief word for word and saves scores back into your workspace, and Terra is the fastest model we test and the first to pass every check in a single run. Sol is the reminder that a polished build can still answer a brief nobody gave. One family ships MIT weights and a single rate. The other ships a three-size ladder and image input. The choice between them is about which measure you need, and about what you want the model to do when your brief goes quiet.
Neither is the winner. The winner is the setup that puts judgment where ambiguity lives and precision where the brief is exact.
▲ Memory feeds Intelligence. ■ Intelligence triggers Execution. ● Execution creates Memory. One open-weight family, one closed one. One workspace. No single point of vendor failure.
This is the origin of living software. 🌱
Build with GLM and GPT in one workspace →
Related reading
- 10 Best Open-Source AI LLMs in 2026: Where GLM sits in the open-weight field.
- History of AI benchmarks: Why every model claims to be best, and how TSK-1 differs.
- GLM vs Claude: GLM against the other closed frontier lab.
- GLM vs DeepSeek: GLM against the other open-weight family we have tested.
- GPT vs Claude: The two closed frontier families, head to head.
- Multi-Model AI Access: How Taskade routes across providers.
- Multi-Agent Teams: Specialists with different model picks.
- Taskade MCP Server: Connect any MCP-compatible IDE to your workspace.
- TSK-1 GLM profile: Full evidence for the GLM family.
- TSK-1 GPT profile: Full evidence for the GPT family.
- TSK-1 hub: The complete model test dataset.