



On June 12, 2026, two tech leads on Google Cloud's data team published a specification that fits on one page. It defines no API and ships no SDK. It says that knowledge for AI agents should be a directory of Markdown files, and that each file must declare one thing: its type.
They called it the Open Knowledge Format, or OKF. Six weeks later, version 0.2 added the fields that record who wrote a file, who checked it, and when it expires. The specification grew from about 2,000 words to about 5,200.
This guide is a reference to the format itself. It quotes the v0.2 specification rule by rule, shows complete example files, and lists what the format leaves unsolved. For the pattern behind OKF and how it compares with retrieval, read the companion guide, LLM Wiki Explained.
TL;DR: The Open Knowledge Format (OKF) is Google Cloud's open spec for agent-readable knowledge, published June 12, 2026. A bundle is a folder of Markdown files, and
typeis the only required field. Version 0.2 adds trust and freshness fields. OKF defines the files and leaves the upkeep to you. Build a knowledge base that agents maintain.
What Is the Open Knowledge Format?
The Open Knowledge Format (OKF) is an open specification from Google Cloud for knowledge that both people and AI agents read. A bundle is a directory of Markdown files. Each file describes one concept and starts with a YAML frontmatter block. It was published on June 12, 2026, and the repository uses the Apache 2.0 license.
The authors are Sam McVeety, Tech Lead for Data Analytics, and Amir Hormati, Tech Lead for BigQuery. Their launch post calls OKF "an open specification that formalizes the LLM-wiki pattern into a portable, interoperable format" and links to Andrej Karpathy's LLM Wiki gist as the source of the idea.
The specification states its own design in three sentences:
"The format is intentionally minimal: a directory of markdown files with YAML frontmatter. There is no schema registry, no central authority, and no required tooling. If you can
cata file, you can read OKF; if you cangit clonea repo, you can ship it."
It names four properties that the format must keep.
| Property | What the spec says | Why it matters for agents |
|---|---|---|
| Readable | "by humans without tooling" | A person can review what an agent wrote |
| Parseable | "by agents without bespoke SDKs" | Any model can load a file into its context |
| Diffable | "in version control" | Every change has an author and a history |
| Portable | "across tools, organizations, and time" | The knowledge outlives the tool that wrote it |
The format separates the party that writes knowledge from the party that reads it. The launch post puts it this way: "OKF cleanly separates who writes the knowledge from who consumes it."
OKF at a Glance: The Whole Spec on One Screen
The whole Open Knowledge Format fits in one table. A bundle is a directory, a concept is a Markdown file, the file path is the concept's ID, Markdown links are the relationships, two file names are reserved, and one frontmatter field is required. Everything else is optional or left to the producer.
| Element | Rule in OKF v0.2 | Required? |
|---|---|---|
| Bundle | A directory tree of Markdown files, shipped as a git repository, an archive, or a subdirectory | Yes |
| Concept | One UTF-8 Markdown file: YAML frontmatter, then a body | Yes |
| Concept ID | The file path within the bundle, with .md removed |
Derived |
type |
A short string that names the kind of concept | Yes, the only one |
title, description, resource, tags |
Display name, one-line summary, URI of the asset, labels | Recommended |
sources, generated, verified |
Provenance and trust | Optional |
status, stale_after |
Lifecycle and freshness | Optional |
| Links | Standard Markdown links between concepts | Optional |
index.md |
Reserved. A listing of one directory | Optional |
log.md |
Reserved. Change history, newest first | Optional |
Three numbers summarize the format as of November 12, 2026.
| Fact | Value |
|---|---|
| Required frontmatter fields | 1 |
| Reserved file names | 2 |
| Conformance rules for a bundle | 3 |
The launch post lists what OKF deliberately does not include: "No complex compression scheme, no new runtime, no required SDK."
How Is an OKF Bundle Laid Out?
An OKF bundle is a directory tree of Markdown files. The specification says the structure "is independent of the domain," so producers organize folders in whatever way fits the knowledge. Two file names, index.md and log.md, are reserved at every level. Every other .md file is a concept.
Here is a small bundle for a company's data and operations knowledge. The layout is our example. The rules it follows are the specification's.
acme-knowledge/                     the bundle root
├── index.md                        reserved: listing of the root
├── log.md                          reserved: change history
├── metrics/
│   ├── index.md
│   ├── active-accounts.md          Concept ID: metrics/active-accounts
│   └── net-revenue.md              Concept ID: metrics/net-revenue
├── tables/
│   ├── index.md
│   ├── accounts.md                 Concept ID: tables/accounts
│   └── invoices.md                 Concept ID: tables/invoices
├── playbooks/
│   └── late-invoice-follow-up.md   Concept ID: playbooks/late-invoice-follow-up
├── computations/
│   └── net-revenue.md              type: Attested Computation
└── references/                     convention: mirrored external material
    └── revenue-policy.md
The Concept ID comes from the path
A concept has no ID field. The specification defines the Concept ID as "the path of the concept's file within the bundle, with the .md suffix removed." Move the file and the ID changes. This is why a git repository is the recommended way to ship a bundle: a rename is visible in history.
| File path | Concept ID |
|---|---|
metrics/active-accounts.md |
metrics/active-accounts |
tables/invoices.md |
tables/invoices |
playbooks/late-invoice-follow-up.md |
playbooks/late-invoice-follow-up |
Three ways to distribute a bundle
| Distribution | Spec status | What you get |
|---|---|---|
| A git repository | Recommended | History, attribution, and diffs |
| A tarball or zip archive | Allowed | One file to hand over |
| A subdirectory in a larger repository | Allowed | Knowledge next to the code it describes |
The two reserved files
The specification says reserved file names "have defined meaning at any level of the hierarchy and MUST NOT be used for concept documents."
An index.md lists a directory so that an agent can see what exists before it opens anything. The specification calls this progressive disclosure. Index files carry no frontmatter, with one exception: the root index may declare the version the bundle targets.
Markdown
---
okf_version: "0.2"
---

# Metrics

* [Active accounts](metrics/active-accounts.md) - Accounts with one or more sessions in the last 30 days
* [Net revenue](metrics/net-revenue.md) - Invoiced revenue minus refunds and credits

# Tables

* [Tables](tables/) - Source tables for accounts and invoices

# More

* [Playbooks](playbooks/) - Steps for operational tasks such as a late invoice
* [Computations](computations/) - Attested calculations behind the metrics
* [References](references/) - Mirrored external material such as the revenue policy
A log.md records what changed in its directory. Entries are grouped by date, newest first, and the specification requires that "date headings MUST use ISO 8601 YYYY-MM-DD form."
Markdown
# Directory Update Log

## 2026-11-10
* **Update**: Changed the refund rule in [Net revenue](/metrics/net-revenue.md).
* **Deprecation**: Marked the old gross revenue metric as deprecated.

## 2026-11-03
* **Creation**: Added the [late invoice playbook](/playbooks/late-invoice-follow-up.md).
The agent reads two short lists and one file. It does not read the other files in the bundle. That navigation pattern is the same one that agent skill files use, and it is why a bundle can grow without filling the model's context.
What Goes in an OKF Concept File?
An OKF concept file has two parts: a YAML frontmatter block between --- lines, and a Markdown body. The frontmatter holds the few fields that tools filter on. The body holds the content that people and models read. The specification says "type is the only always-required key; a concept carrying just type is fully conformant."
The smallest valid concept is three lines.
Markdown
---
type: Playbook
---
Field reference: identity
| Key | Status | Meaning | Example |
|---|---|---|---|
type |
Required | The kind of concept. Used for routing, filtering, and presentation | Metric |
title |
Recommended | Display name. A reader may derive one from the file name | Net revenue |
description |
Recommended | One sentence. Used by index generators and search snippets | Invoiced revenue minus refunds. |
resource |
Recommended | A URI for the asset the concept describes. Absent for abstract ideas | https://example.com/tables/invoices |
tags |
Recommended | A list of short labels | [finance, revenue] |
The specification gives example type values: "BigQuery Table, BigQuery Dataset, API Endpoint, Metric, Playbook, Reference, Attested Computation." It then adds the sentence that shapes the whole format: "Type values are not registered centrally."
Field reference: provenance, trust, and lifecycle (new in v0.2)
| Key | Status | Meaning | Example |
|---|---|---|---|
sources |
Optional | The materials the concept derives from | A list of entries, each with a resource |
usage_window |
Optional | The date range that frames every usage_count |
{ from: ..., to: ... } |
generated |
Optional | Who or what produced the current content, and when | { by: human:mlee, at: 2026-11-10T09:00:00Z } |
verified |
Optional | A list of confirmations, each with by and at |
- { by: human:rkhan, at: ... } |
status |
Optional | draft, stable, or deprecated. Absent means stable |
stable |
stale_after |
Optional | The instant after which the content is stale | 2027-02-01T00:00:00Z |
Each entry in sources has its own small schema.
Key in a sources entry |
Status | Meaning |
|---|---|---|
resource |
Required within an entry | A URL, a bundle path, or a scope such as "all queries in project X" |
id |
Optional | A stable key that body footnotes cite |
title |
Optional | A label for the source |
author |
Optional signal | Who or what produced the source |
usage_count |
Optional signal | How often the source was used in the usage window |
last_modified |
Optional signal | When the source itself last changed |
A complete v0.2 concept file
This file uses every general-purpose v0.2 field. The content is our example. The keys, the actor names, and the timestamp form follow the specification, which requires that every timestamp is "an ISO 8601 datetime with an explicit UTC offset."
Markdown
---
type: Metric
title: Net revenue
description: Invoiced revenue minus refunds and credits, by calendar month.
resource: https://example.com/dashboards/net-revenue
tags: [finance, revenue, monthly]
status: stable
generated: { by: catalog_agent/2.1, at: 2026-11-10T09:00:00Z }
verified:
  - { by: process:finance-nightly, at: 2026-11-11T02:00:00Z }
  - { by: human:rkhan, at: 2026-11-11T15:30:00Z }
stale_after: 2027-02-01T00:00:00Z
sources:
  - id: revenue-policy
    resource: /references/revenue-policy.md
    title: Revenue recognition policy
    author: team:finance
    last_modified: 2026-10-02T00:00:00Z
  - id: revenue-dashboard
    resource: https://example.com/dashboards/net-revenue
    title: Net revenue dashboard
    author: team:finance
    usage_count: 1200
    last_modified: 2026-11-08T00:00:00Z
usage_window: { from: 2026-10-01T00:00:00Z, to: 2026-10-31T00:00:00Z }
---

# Definition

Net revenue is the sum of paid invoices in a calendar month, minus refunds
and credits issued in the same month.[^revenue-policy] It is computed by
[the net revenue computation](/computations/net-revenue.md).

# Schema

| Field         | Type    | Description                          |
|---------------|---------|--------------------------------------|
| `month`       | DATE    | First day of the calendar month.     |
| `net_revenue` | NUMERIC | Revenue in US dollars.               |

# Examples

Finance reads this metric from the net revenue dashboard.[^revenue-dashboard]
Join to [accounts](/tables/accounts.md) on `account_id` for a segment view.

[^revenue-policy]: Revenue recognition policy
[^revenue-dashboard]: Net revenue dashboard
Three details in that file are easy to miss.
Actors have a fixed form. The specification defines <producer>/<version> for agents, human:<id> for people, and process:<id> for automated processes. Trust tiers depend on the human: prefix, so "producers MUST use it for hand-authored or human-confirmed content."
Footnotes are keyed by ID. A claim cites a source with a footnote whose label is a sources ID. The specification explains why a position number is not used: "agents constantly rewrite these documents: a positional index misattributes silently the moment the list is reordered, whereas a stable id survives reordering."
No credibility score is stored. OKF records the author, the usage count, and the last-modified date of each source. It records no rating. The specification gives the reason: "a score is subjective, unportable across consumers, and goes stale."
The body has no required sections. Three headings have a conventional meaning: # Schema, # Examples, and # Computation.
How Do Links Turn an OKF Bundle Into a Graph?
OKF concepts link to each other with standard Markdown links, and those links are the graph. The directory tree gives each concept a parent. Links add every other relationship. The specification says a link "asserts a relationship" and that tools which draw a graph "typically treat all links as directed edges of an untyped relationship."
| Link form | Example | Spec status |
|---|---|---|
| Absolute, bundle-relative | [accounts](/tables/accounts.md) |
Recommended |
| Relative | [neighbor](./other.md) |
Supported |
The link itself carries no label. The specification says the kind of relationship, such as joins-with or depends-on, "is conveyed by the surrounding prose, not by the link itself." A person or a model can read the sentence. A program that reads only the edge cannot tell a join from a citation.
The gray node is legal. A link to a file that does not exist is not an error in OKF. The rule reads: "Consumers MUST tolerate broken links: a link whose target does not exist in the bundle is not malformed; it may simply represent not-yet-written knowledge." A classic wiki works the same way, with links to pages that nobody has written yet.
Lineage also runs through links. When a sources entry points at another concept in the bundle, a reader can follow it to that concept's own sources. No separate lineage field exists in v0.2. For typed edges and rules about what may connect to what, see knowledge graphs for AI agents.
What Must an OKF Reader Tolerate?
An OKF reader must accept imperfect bundles. The specification gives producers three hard rules and tells consumers to treat almost everything else as soft guidance. A reader may not reject a bundle for missing optional fields, unknown types, unknown keys, broken links, or missing index files. The format is strict about very little, on purpose.
The conformance section is short enough to quote in full. A bundle is conformant with OKF v0.2 if:
- "Every non-reserved
.mdfile in the tree contains a parseable YAML frontmatter block." - "Every frontmatter block contains a non-empty
typefield." - "Every reserved filename (
index.md,log.md) follows the structure in §8 and §9 respectively when present."
Then comes the list of things a consumer cannot refuse. The specification says "consumers MUST NOT reject a bundle because of" these five conditions:
- "Missing optional frontmatter fields."
- "Unknown
typevalues." - "Unknown additional frontmatter keys."
- "Broken cross-links."
- "Missing
index.mdfiles."
| Party | Must | Should |
|---|---|---|
| Producer | Give every concept parseable frontmatter and a non-empty type |
Pick descriptive types, and prefer headings, lists, and tables over free prose |
| Producer | Use the human: prefix for human-written or human-confirmed content |
Give each cited source an id |
| Consumer | Tolerate unknown types, unknown keys, and broken links | Preserve unknown keys when it rewrites a file |
| Consumer | Treat a single verified mapping as a list of one |
Show a failing attestation, never hide it |
| Consumer | Never reject a concept for a missing optional family | Try best-effort reading of a version it does not know |
The first version of the specification explained the choice in one sentence: "This permissive consumption model is intentional: OKF is meant to remain useful as bundles grow, get refactored, and are partially generated by agents."
Three common misreadings
| Claim you may have read | What the specification says |
|---|---|
| Readers must accept files they cannot parse | Parseable frontmatter is conformance rule 1. The tolerance list does not include unparseable files |
| Google loosened the rules after launch because agents write messy files | The tolerance list is in v0.1, from the first published version |
| The rules got looser in v0.2 | One got stricter. v0.1 said readers "SHOULD NOT reject documents with unrecognized fields." v0.2 says "MUST NOT" |
The design follows an old rule of network engineering: be careful in what you write and generous in what you read. For an agent, the same split has a sharper form. Reading a messy file costs a retry. Writing a wrong fact into the record costs every later answer. OKF covers the reading half. The writing half needs checks that OKF does not define, which is the subject of why AI agents need an ontology.
What Changed From OKF v0.1 to v0.2?
OKF v0.2, published on July 24, 2026, adds optional frontmatter that answers five questions about a concept: where it came from, how much to trust it, whether it is still true, whether it is current, and whether a number was computed the approved way. The v0.2 announcement says the release "adds vocabulary, not rules."
The reason is stated in the specification's motivation section. A knowledge corpus is now "continuously written and maintained by agents," and "when most concepts are machine-generated, a consumer needs answers that a plain markdown-plus-frontmatter convention does not make first-class."
| Question | Family | Fields added in v0.2 |
|---|---|---|
| What was this created from? | Provenance | sources, usage_window, per-source author, usage_count, last_modified |
| How much should I trust it? | Trust | generated, verified, and the actor convention |
| Is it still true? | Freshness | stale_after |
| Is it the current version? | Lifecycle | status |
| Was this number produced the approved way? | Attestation | The Attested Computation type and its keys |
The specification itself more than doubled in length.
The counts come from the two SPEC.md files: the v0.1 file at its launch commit, and the current v0.2 file read on November 12, 2026.
The two breaking changes
The specification calls v0.2 a minor version bump "except for two deliberate breaking changes."
| v0.1 | v0.2 | Fallback for old bundles |
|---|---|---|
timestamp in frontmatter |
generated: { by, at } |
A reader may fall back to timestamp when generated is absent |
A # Citations list in the body |
sources in frontmatter, cited by footnote |
A reader may still parse a # Citations list |
Everything else from v0.1 is "carried forward unchanged": the bundle structure, the reserved file names, the required type, linking, index files, log files, and the permissive conformance rules.
Trust tiers
A reader derives a trust tier from the verified field. Nothing stores the tier. The specification is explicit that "trust tiers are advisory signals, not access control."
| Tier | Rule | Example use |
|---|---|---|
| Unverified | No verified key |
Show with a warning label |
| Machine-confirmed | Verified by non-human actors only | Allow in internal agent answers |
| Human-reviewed | Verified by a human:<id> actor |
Allow in an executive dashboard |
Status and staleness
status moves a concept through three values. stale_after is one absolute instant, and "a concept is stale when now >= stale_after." The authors chose a fixed instant over a time-to-live so that the check is a plain comparison.
Attested Computation
The largest addition is a new concept type. An Attested Computation carries an approved way to compute a value, so that a reader can confirm that an agent ran that computation and did not write its own query. The specification is careful about scope: "OKF records the computation and the means to check it; it does not execute anything itself."
| Key | Status for this type | Meaning |
|---|---|---|
runtime |
Required | How to run the computation, for example bigquery, postgres, dbt, python |
parameters |
Optional | The typed, named values an agent may supply |
computation |
Optional | A path to a file that holds the computation. Absent means the body holds it |
executor |
Optional | Run instructions, and the receipt fields a run must return |
attester |
Optional | Deterministic code, with no LLM, that checks a receipt |
The rule for agents is strict: "The agent MAY only supply values for the declared parameters; it MUST NOT author or edit the computation."
Verification and attestation are different checks. verified confirms that a definition still matches policy, and it is stored in the bundle. Attestation confirms that one run produced the value the approved way, and it is never stored. The specification notes that "a concept with a stale definition can still attest cleanly."
Several parts are left for a later version: the wire format for receipts and verdicts, sandboxing for attesters, and caching.
How Does OKF Compare With llms.txt, AGENTS.md, MCP, JSON-LD, and RDF?
OKF is one of several formats that help AI systems read what an organization knows, and each one standardizes a different thing. OKF standardizes how knowledge is written down as files. It does not replace instructions for a coding agent, a protocol for tool calls, markup for web pages, or a formal ontology language.
| Format | What it standardizes | Who reads it | Where it lives |
|---|---|---|---|
| OKF | Knowledge as typed Markdown files with links | Agents and people inside or between organizations | A folder or a git repository |
| llms.txt | A curated index of a website for language models | AI systems that read the public web | One file at a site's root |
| AGENTS.md | Instructions for a coding agent in a project | Coding agents | The root of a code repository |
| MCP | How an agent calls tools and reads data sources | Agent runtimes | A running server |
| schema.org JSON-LD | Structured facts about a web page | Search engines and answer engines | Inside a page's HTML |
| RDF and OWL | Formal statements and logic about a domain | Reasoners and graph databases | Triple stores and ontology files |
Two comparisons deserve a closer look.
OKF and MCP solve different halves. The Model Context Protocol defines how an agent reaches a system. OKF defines what the agent reads when it gets there. One way to hold the difference: MCP is the pipe, and an OKF bundle is the cargo. One community project already pairs them. Kiso describes itself as a publishing engine and MCP server for OKF bundles. This is our analysis. Google's launch post does not mention MCP.
OKF and RDF sit at opposite ends. RDF and OWL give every relationship a name and a formal meaning. OKF gives relationships no label at all. A reader on the Hacker News launch thread made the link with some humor: "I love revisiting RDF/OWL Semantic Web formats every 10 years." OKF's bet is that models read prose well enough that typed edges can wait. The cost of that bet appears in the open problems below.
The first version of the specification placed OKF next to three existing patterns: LLM wiki repositories, personal knowledge tools "like Obsidian and Notion," and "metadata as code." It then named the one difference: "OKF differs primarily in being specified." For the history of the file format underneath all of this, see the history of Markdown.
Does OKF Replace RAG or a Vector Database?
No. OKF does not replace retrieval-augmented generation or a vector database. The specification lists "Prescribing storage, serving, or query infrastructure" as a non-goal. OKF defines how knowledge is written into files. How an agent finds the right file is left to whoever consumes the bundle.
Google's launch post does not mention RAG or vector search. The repository's README lists "a search index" as one valid way to consume a bundle, next to a file server, a wiki tool, and a model that loads files into its context.
| Bundle size | How an agent usually finds a concept |
|---|---|
| Tens of concepts | Reads the root index.md, then opens files |
| Hundreds | Reads per-folder index files, plus text search |
| Thousands and more | Uses a search or retrieval system built over the bundle |
So the claim that "a folder beats the vector database" is a claim about the LLM wiki pattern at moderate size. It is not a claim that the specification makes. The full comparison, with the evidence and a decision table, is in LLM Wiki Explained. For the retrieval side, see the history of RAG and vector databases explained.
How Do You Write an OKF Bundle by Hand in 20 Minutes?
You can write a conformant OKF bundle in about 20 minutes with a text editor and git. Start with five concepts on one subject. Decide your type names before you write the first file. The format will accept any types, so the discipline has to come from you.
- Create the folder and start a repository. Make a directory and run
git init. The specification recommends git, since it gives history and attribution. - Choose your types. Write a short list of 5 to 10 type names and what each one means. Put it in a
references/types.mdconcept. OKF has no type registry, so this file is your registry. - Write one concept with only a type. Create
metrics/net-revenue.mdwith a frontmatter block that holdstype: Metric. The bundle is now conformant. - Add the recommended fields. Add
title, a one-sentencedescription, andtags. Addresourceif the concept describes a real asset. - Write the body with structure. Use headings, lists, and tables. The specification says structure "aids both human reading and agent retrieval."
- Link concepts. Use bundle-relative links that start with
/. Say what the relationship is in the sentence around the link. - Add the root index. Create
index.mdwith one line per concept, and declareokf_version: "0.2". - Add the log. Create
log.mdwith today's date as an ISO heading and one line per change. - Add trust fields. Give each concept
generated, and addverifiedandstale_afterwhere a person has checked the content. - Check and commit. Run the checklist below, then commit.
| Check | Level | How to test |
|---|---|---|
| Every concept file has frontmatter that parses | Spec: required | Load each file with a YAML parser |
Every concept has a non-empty type |
Spec: required | Search for files with no type: line |
No concept is named index.md or log.md |
Spec: required | List file names |
Log date headings use YYYY-MM-DD |
Spec: required | Search the log headings |
| Timestamps carry an explicit UTC offset | Spec: required for timestamp keys | Search for at: values with no Z or offset |
Human actors use the human: prefix |
Spec: required for producers | Search by: values |
Every type is on your list |
Our advice | Compare against references/types.md |
| Every link target exists | Our advice. Broken links are legal | Run a link checker |
Every concept has an owner and a stale_after |
Our advice | Search for files with no stale_after |
The last three rows are stricter than the specification. That is deliberate. A reader must forgive those problems. A writer who wants a useful bundle should not create them.
What Tooling Exists for OKF?
OKF tooling is early. Google ships three reference pieces in the repository: an enrichment agent that writes bundles, a static visualizer that reads them, and sample bundles. A small set of community tools adds linting, a command-line client, signing, and publishing. On November 12, 2026, the repository had 1,471 stars and 98 forks.
| Reference piece | What it does | Note |
|---|---|---|
| Reference enrichment agent | Walks a BigQuery dataset and drafts one concept per table and view, then enriches concepts from documentation pages | Needs BigQuery access and a Gemini key or Vertex AI |
| Static visualizer | Turns a bundle into one self-contained HTML file with a graph, a detail panel, and backlinks | Built with Cytoscape.js. No backend |
| Sample bundles | GA4 e-commerce, Stack Overflow, Bitcoin, and Acme Retail | All four carry the v0.2 fields. Acme Retail is the worked example in the v0.2 announcement |
Google describes all three as proofs of concept. The launch post says "nothing about the format requires a specific agent framework or LLM."
Community tools found through Hacker News, with star counts read on November 12, 2026:
| Tool | What it says it does | Stars |
|---|---|---|
| okf-lint | A linter for OKF bundles | 8 |
| okfctl | A CLI to author, validate, lint, and search bundles | 8 |
| Kiso | A publishing engine, MCP server, and Java library for OKF | 56 |
| signed-okf | Signed provenance for bundles | Not read |
| Kage | Verification and freshness checks for OKF agent memory | Not applicable |
The numbers are small, and it is fair to say so. The v0.2 announcement reports that contributors "opened extension proposals (typed relationship edges, agent-routing hint fields, an optional erasure conformance profile, an .okfignore convention, and more)." It names no outside adopters. A format becomes a standard when a second and a third party write tools that agree, and that work has only started.
Because a bundle is Markdown with frontmatter, tools that were never built for OKF can still open one. Any editor, any static site generator, and note apps such as Obsidian can show the files. Any agent that can read a folder can use the index files. That reach is the main benefit of choosing the plainest possible format.
What Are the Open Problems in OKF?
OKF leaves five problems open: types have no shared meaning, freshness fields have no process behind them, the format has no access control, the Markdown dialect is not specified, and one vendor controls the roadmap. None of them breaks the format. Each one moves work to the people who adopt it.
| Open problem | What the spec says | What it means for you |
|---|---|---|
| Types have no shared meaning | "Type values are not registered centrally" | Two teams can write valid bundles that cannot be combined |
| Links have no labels | Edges are "an untyped relationship" | A program cannot tell a join from a citation |
| Freshness has no runner | stale_after is a comparison a reader may make |
Something else must rebuild expired concepts |
| No access control | Trust tiers are "not access control" | Everyone who can read the folder reads everything |
| Markdown dialect unspecified | The body is "standard markdown" | Tables and footnotes may render differently across tools |
| Governance | The repository belongs to Google Cloud | The roadmap depends on one vendor for now |
Types need a vocabulary. The one required field is a free-form string. One team writes BigQuery Table, another writes Table, a third writes Relational asset. All three are conformant. An agent that reads all three bundles has no way to know that they mean the same thing. OKF standardizes the container. A shared list of types and rules, which is an ontology, has to be supplied by the people who write the bundles. A fixed taxonomy is a stated non-goal, so this gap is by design.
A field is not a process. stale_after: 2027-02-01T00:00:00Z tells a reader when to stop trusting a concept. It does not rebuild the concept. Nothing in the format wakes up on that date. The v0.2 fields tell you which concepts expired. A scheduled job, a person, or an agent has to act on them.
OKF defines the first two boxes. The pink boxes are outside the format.
The Markdown question came up on day one. On the Hacker News launch thread, which reached 87 points, one reader asked: "Is the flavor of Markdown (e.g. CommonMark) specified?" Another wrote: "You can't represent knowledge well without a graph format showing labeled relationships between entities." A third was less patient: "Google has announced… Markdown with YAML front-matter, ladies and gentlemen." A reply in the same thread gave the case for the choice, that Markdown is "the lowest common denominator for both human and AI models."
The version numbers contradict the versioning rule. The specification says a minor version adds "backward-compatible additions" and that breaking changes belong to a major version. It then ships two breaking changes in a minor release, and says so. For a version 0 draft this is a small point, and the fallbacks are defined. It does show that the format is still moving.
Who Is Behind OKF, and Why?
OKF comes from Google Cloud's data analytics group, the team behind BigQuery. It does not come from Google's AI research labs. Both announcement posts are signed by Sam McVeety and Amir Hormati and published under the Data Cloud name. That origin explains the format's examples, its first tools, and its most developed feature.
| Fact | Source |
|---|---|
| Authors lead Data Analytics and BigQuery engineering | Bylines of both Google Cloud posts |
| Launch sample bundles describe BigQuery public datasets | Launch post and repository |
| The reference agent uses Gemini through AI Studio or Vertex AI | Repository README |
| Knowledge Catalog can ingest OKF and serve it to agents | Launch post |
| Dataplex Universal Catalog became Knowledge Catalog on April 10, 2026 | Google Cloud documentation |
A data team has a specific problem that a personal wiki does not. An agent that answers "what was revenue last quarter" must know which table to query, what the columns mean, and which definition of revenue finance has approved. That knowledge usually lives in a catalog, in old pull requests, and in people's heads. OKF is a way to write it down next to the data. Attested Computation, the largest part of v0.2, is a direct answer to a finance team's worry that an agent will invent its own SQL.
The openness is real and so is the commercial interest. The launch post says OKF "will never require a proprietary account or SDK to read, write, or serve," and the README lists other vendors' catalogs as valid sources. The same post says Google's catalog product already ingests the format. Both statements can be true. A company can publish an open format and also want to be the best place to use it. GitHub did not own git, and it still became the place where most people use it.
For a team that evaluates OKF, the practical reading is simple. The files are yours and they are plain text. If the standard stalls, you still have a well-organized folder of Markdown.
What Does OKF Mean for a Team Knowledge Base?
For a team, OKF settles the easy half of a knowledge base and leaves the hard half open. The easy half is the shape of the files. The hard half is the work around them: who writes each page, who checks it, what runs when a page expires, and who may see it. A format cannot do that work.
Those four needs map to four parts of a working system.
| Need | What OKF gives | What still has to exist |
|---|---|---|
| A place for knowledge | A folder and a file per concept | Storage that the whole team can reach |
| Someone to write and update | A generated field |
An agent or a person who does the writing |
| Something that runs on a schedule | A stale_after field |
A scheduler that acts on the date |
| Control over who sees what | Nothing | Roles and permissions |
One clear statement first: Taskade does not read or write OKF bundles. It takes a different route to the same goal. In a Taskade workspace, projects are the pages, AI agents read those projects as knowledge and update them, automations run the checks on a schedule, and role-based access from Owner to Viewer controls who can change what. The missing runner is part of the product. Automations run on every plan, and agent work uses AI credits.
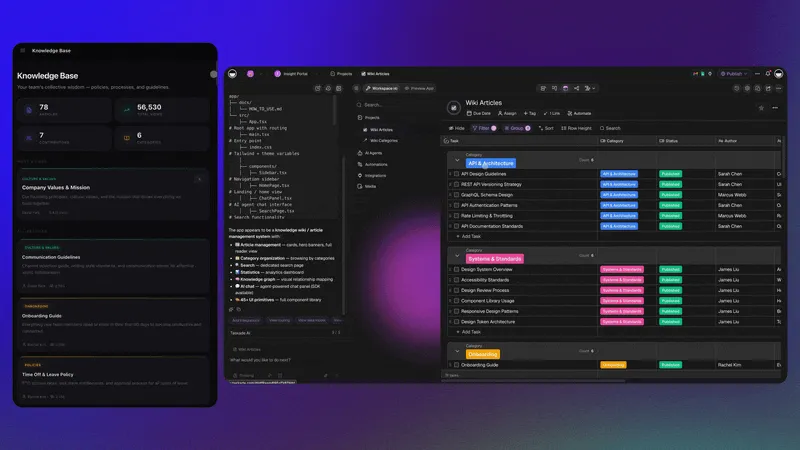
The two approaches fit different teams. A data team that lives in git and wants knowledge next to its SQL is well served by a bundle. A team that wants a shared knowledge base with agents and schedules, and no terminal, is better served by a workspace. The ideas carry over in both directions. Give every page a type from a short list, an owner, and a review date, whatever tool you use. For product options, see the best AI wiki tools. For the larger argument, see the workspace as a runtime.
Frequently Asked Questions
What is the Open Knowledge Format (OKF)?
The Open Knowledge Format is an open specification from Google Cloud, published on June 12, 2026, for knowledge that people and AI agents both read. A bundle is a directory of Markdown files. Each file is one concept with a YAML frontmatter block, and the only required field is type. The repository uses the Apache 2.0 license.
What is the only required field in OKF?
The only required field in OKF is type, a short string that says what kind of concept the file describes, for example Metric or Playbook. The specification states that a concept carrying just type is fully conformant. Title, description, resource and tags are recommended. Every trust and lifecycle field is optional.
Is OKF the same as an LLM wiki?
No. Google describes OKF as an open specification that formalizes the LLM wiki pattern into a portable format. OKF defines the files: the folder, the frontmatter and the links. Andrej Karpathy's LLM wiki pattern also covers the raw sources, an instruction file for the agent, and the ingest, query and lint routines that keep the pages current.
Does OKF replace RAG?
No. The OKF specification lists storage, serving and query infrastructure as non-goals. OKF defines how knowledge is written down. It does not define how an agent finds the right file. A small bundle can be read through its index files, and a large bundle can still be indexed by a search or retrieval system.
What changed in OKF v0.2?
OKF v0.2, released on July 24, 2026, added optional frontmatter for provenance, trust and lifecycle: sources, generated, verified, status and stale_after. It added a new concept type, Attested Computation. It also replaced two v0.1 conventions: timestamp became generated.at, and the body Citations list became the sources field.
Is OKF only for Google Cloud?
No. The launch post says OKF is not tied to any specific cloud, database, model provider or agent framework, and a bundle is plain Markdown that any tool can read. In practice the reference agent reads BigQuery and uses Gemini, and Google Cloud's Knowledge Catalog can ingest bundles, so the shortest path today runs through Google products.
Is OKF an SEO format?
No. OKF is a format for knowledge that agents and people read inside an organization or exchange between systems. It gives a search engine no ranking signal. The formats that address web crawlers and web-facing AI systems are schema.org structured data and llms.txt, which solve a different problem.
What license is OKF under?
The Open Knowledge Format repository on GitHub is licensed under Apache 2.0. The specification, the reference enrichment agent, the static visualizer and the sample bundles are all in that repository. The launch post says the format will never require a proprietary account or SDK to read, write or serve.
What are index.md and log.md in OKF?
They are the two reserved file names in OKF. An index.md file lists the contents of a directory with one short description per entry, so an agent can see what exists before it opens files. A log.md file records changes to that directory, newest first, under date headings. Both files are optional.
Does OKF keep knowledge up to date?
No. OKF v0.2 lets a concept record when it expires with stale_after and who confirmed it with verified. Those are fields in a file. The specification does not run anything. A person, a scheduled job or an AI agent still has to notice an expired concept, rebuild it from its sources and verify it again.
A Format Is a Promise, Not a Practice
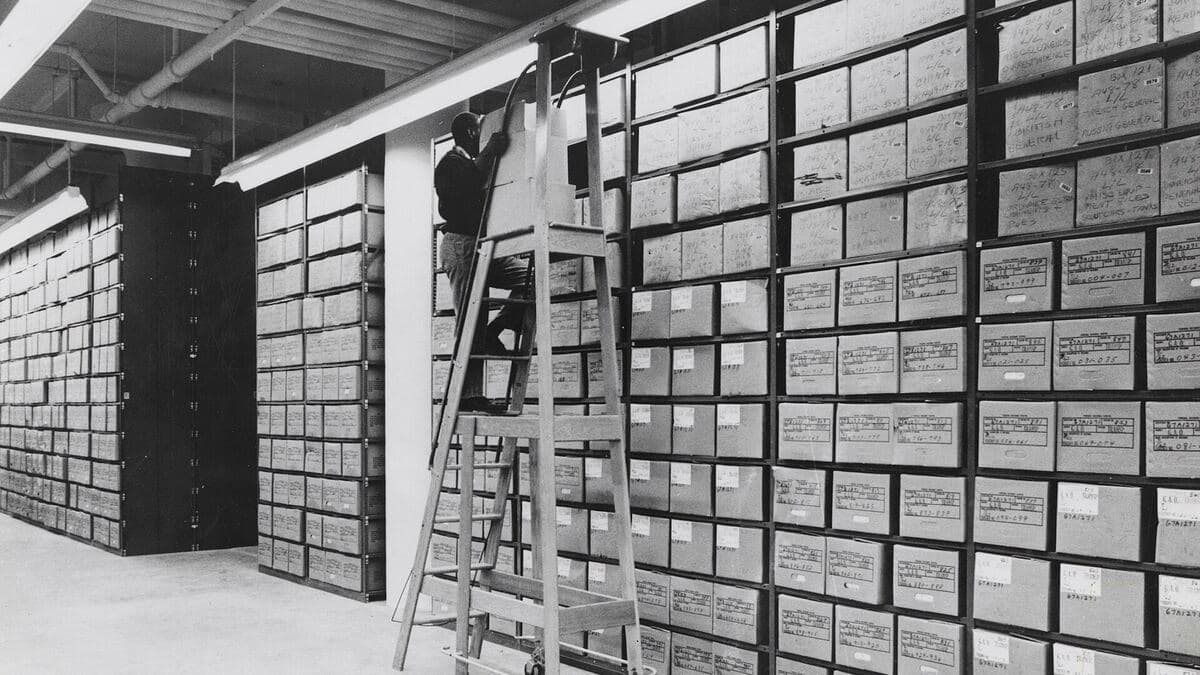
The picture at the top of this page shows an archivist on a ladder in a federal records center. Every box on those shelves has a label and a place. The shelves did not file the boxes. A person did, one box at a time, and then someone kept doing it.
OKF is the label and the shelf. It is a small, sensible agreement about how to write knowledge down so that any model and any person can read it. It is worth adopting for that alone. The upkeep, the checking, and the shared vocabulary are still your job, or the job of the agents and schedules you set up to do them.
That loop is what a workspace is for. Projects hold what the team knows. Agents read and write it. Automations keep it current. Memory, Intelligence, Execution. ▲ ■ ●
Build a knowledge base that agents maintain →
Further Reading
The pattern and the alternatives
- LLM Wiki Explained: Karpathy's pattern, and when a folder beats RAG
- The History of RAG
- LLM vs RAG vs AI Agent vs Agentic AI
- Fine-Tuning vs RAG
Structure and meaning
- Why AI Agents Need an Ontology
- Knowledge Graphs for AI Agents
- Context Engineering Field Guide
- Agent Harness Explained
- AI Agent Memory
Build with it
- AI App Builder: one prompt, one working app
- AI Agents: agents that read your workspace
- Automations: scheduled work across 100+ integrations
- Taskade App Factory: clone a working app and change it
Sources
- Google Cloud, Open Knowledge Format specification, version 0.2. Read on November 12, 2026. All v0.2 quotes come from this file.
- Google Cloud, Open Knowledge Format specification, version 0.1, launch snapshot, June 12, 2026.
- Sam McVeety and Amir Hormati, Introducing the Open Knowledge Format, Google Cloud blog, June 12, 2026.
- Sam McVeety and Amir Hormati, Open Knowledge Format v0.2 tackles agentic trust, Google Cloud blog, July 24, 2026.
- Google Cloud, Open Knowledge Format repository and README. Star and fork counts read on November 12, 2026.
- Google Cloud documentation, Transition from Dataplex Universal Catalog to Knowledge Catalog.
- Andrej Karpathy, LLM Wiki, GitHub gist, April 4, 2026.
- Hacker News, Google proposes Open Knowledge Format based on Markdown, June 13, 2026, and OKF v0.2 thread, July 26, 2026.
- Community tools: okf-lint, okfctl, Kiso, signed-okf, and Kage. Descriptions are each project's own.
- llms.txt and AGENTS.md, project sites.