download dots

DeepSeek V4.1 Flash vs GPT-5.6 Luna

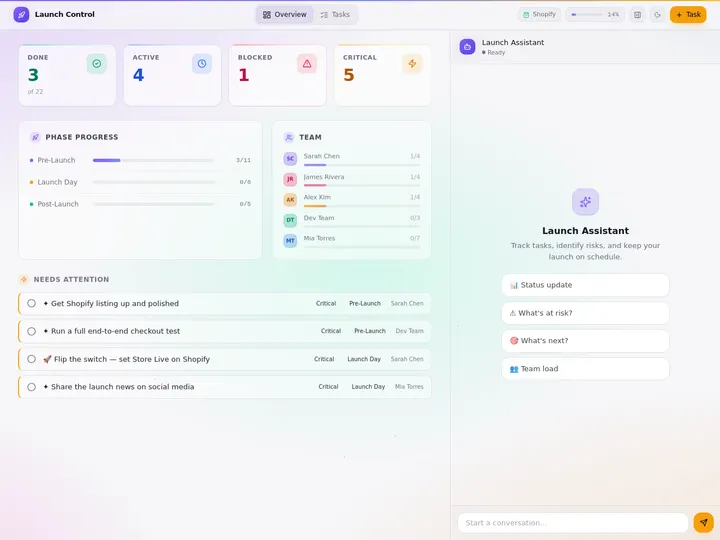
DeepSeek V4.1 Flash and GPT-5.6 Luna are two economical models in Taskade. They took the same requests in Taskade Genesis three times in September 2026: a recipe box, a match tracker, and a real customer's family intake form. In the two tests where we compared time and cost, Luna finished faster and at the lower cost, and Flash built more pages and more automations. This page shows the results, one build per model per test.

Last updated: October 2026

Quick Comparison Table

DeepSeek V4.1 Flash (DeepSeek) GPT-5.6 Luna (OpenAI)
Weights Open-weight family Closed, API only
Shared tests in Sep 2026 3 (one build each) 3 (one build each)
Family intake form, Sep 30, 2026 Every answer and both photos saved on a two-page form, alert automation ran twice, ran past the 15-minute limit Every answer and both photos saved, the most economical complete build, public assistant named a child
Match tracker, Sep 22, 2026 Three pages, coaching automation wrote a note into the first match Two pages in 8 min 19 s, the fastest and most economical complete build
Recipe box, Sep 19, 2026 Printed cookbook with 13 recipes, four pages, both automations live Warm printed cookbook in light and dark, every page loading cleanly
Follow-up change on the intake form Landed and went live Landed cleanly
Best for Richer apps with automations that run Fast, economical builds that stick to the brief

TL;DR: In both September 2026 tests where we compared time and cost, GPT-5.6 Luna was the quicker or more economical finish and DeepSeek V4.1 Flash built the richer app. On the Sep 30, 2026 intake form both saved every answer and both photos, and both follow-up changes went live. Luna's public assistant named a child to a visitor, and Flash's build ran past the 15-minute limit. Try the same kind of request in Taskade Genesis.


What TSK-1 Found

Each test sends one request, word for word, to every model in it. We open every app, use it the way a customer would, and read what it saved back before we record a result. These are the tests that both models took.

Test Model What the app did Result
Family intake form, Sep 30, 2026 DeepSeek V4.1 Flash Saved every answer and both photos on a two-page form, and the follow-up change landed. The build ran past the 15-minute limit. Works, with gaps
Family intake form, Sep 30, 2026 GPT-5.6 Luna The most economical complete build: every answer and both photos saved. Its public assistant told a visitor a child's name. Works, with gaps
Match tracker, Sep 22, 2026 DeepSeek V4.1 Flash Three pages, and its coaching automation wrote a note into the first match logged. Works
Match tracker, Sep 22, 2026 GPT-5.6 Luna The fastest and most economical complete build, in 8 minutes 19 seconds. A match saved from the app came back with all eight details. Works
Recipe box, Sep 19, 2026 DeepSeek V4.1 Flash A printed cookbook with 13 recipes across four pages, and both automations live. Works
Recipe box, Sep 19, 2026 GPT-5.6 Luna A warm printed cookbook in light and dark, with every page loading cleanly. Works

One build per model in each test. See the full evidence at /tsk/deepseek, /tsk/gpt, and the TSK-1 hub.


The Family Intake Form (Sep 30, 2026)

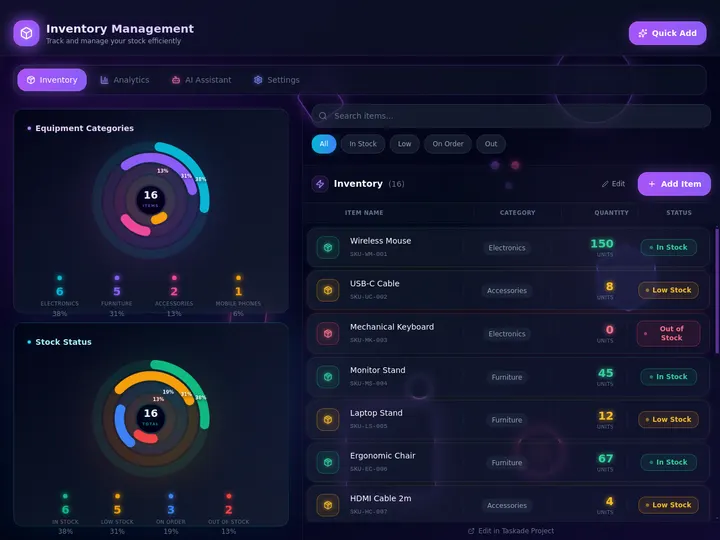
Both models saved everything a parent sent. The request came from a real customer: parents fill in a form on their phone with two to four photos, and the teacher sees every family on one page. Both forms saved every answer and both photos, and both added the new teacher question when we asked for it.

GPT-5.6 Luna got there as the most economical complete build of the test. Its miss was about privacy, not data: its public class assistant told an anonymous visitor a child's name from a saved form. An owner has to close that before the app goes out.

DeepSeek V4.1 Flash built a two-page form, and its alert automation ran twice. The build ran past our 15-minute test limit before it finished, although the app it wrote worked and its follow-up change went live.


The Match Tracker (Sep 22, 2026)

This is the cleanest picture of the trade-off. One player logs each game with hero, result and notes, and a dashboard shows win rate and streaks.

GPT-5.6 Luna built a two-page tracker in 8 minutes 19 seconds, the fastest and most economical complete build of the test. A match saved from the app came back with all eight details in place.

DeepSeek V4.1 Flash built three pages, and its coaching automation ran on the first match logged. About six minutes later it wrote a coaching note back into that match. Luna's app was the quicker, leaner finish. Flash's app did more on its own once someone used it.


The Recipe Box (Sep 19, 2026)

In the recipe-box test, seven models built a recipe box and every one came out as a warm printed cookbook. Luna's rendered cleanly in light and dark, with every page loading. Flash's held 13 recipes across four pages, with both automations live.

Other September results are not head-to-heads, because the two models did not build the same request, but they point the same way. DeepSeek V4.1 Flash built the richest sales CRM of its test, six pages with a scoring automation that scored all 7 sample leads. GPT-5.6 Luna built a fleet-inspection app with both weekly automations live in 7 minutes 18 seconds, and passed all five follow-up-edit tests on its habit tracker.


Choose DeepSeek V4.1 Flash If…

  • You want more app per request. It built three pages where Luna built two on the match tracker, and a four-page cookbook with both automations live.
  • Automations have to run on real entries. Its coaching automation wrote a note into the first match logged, and its intake alert automation ran twice.
  • You can give the build more time. Its intake build ran past the 15-minute limit, and the app it wrote still saved everything.

Choose GPT-5.6 Luna If…

  • Speed matters. It was the fastest complete build of the match-tracker test, at 8 minutes 19 seconds.
  • Cost matters. It was the most economical complete build in both the match-tracker and the intake-form tests.
  • The brief is detailed. Luna is the most faithful model we have tested. It has reproduced all 32 questions of a real customer's sign-up form word for word, and it passed every September follow-up-edit test.
  • You will review the public assistant before sharing. Its intake app was complete, and the one fix it needed was in what its public assistant would say.

The Taskade Angle: Route, Don't Standardize

Taskade routes across frontier models from top AI labs inside one workspace, and you set the model per agent or per automation step. A fast first build on GPT-5.6 Luna and a richer automation pass on DeepSeek V4.1 Flash can share one app, one set of projects, and one memory. Leave a step on TSK-1 Auto and Taskade picks the model for you.


Final Word: The Quick Finish vs the Richer App

GPT-5.6 Luna and DeepSeek V4.1 Flash took the same requests three times in September 2026, and the pattern held. Luna was the fast, economical finish that sticks to the brief, with one privacy miss to fix on the intake form. Flash was the richer app with automations that ran, and it needed more time. One build per model per test, so treat it as a direction. We will add builds as new tests run.

▲ Memory feeds Intelligence. ■ Intelligence triggers Execution. ● Execution creates Memory. Two economical models. One workspace.

Build your own app in Taskade Genesis →


TSK-1 Benchmark

Same request, both models

In the TSK-1 Benchmark, every model receives the same app request, word for word: build a working app that keeps what people enter, runs an automation, and answers questions about its own data, then take a follow-up change. Here is how DeepSeek V4.1 Flash and GPT-5.6 Luna did, tested inside Taskade Genesis.

Same test, same day ·

A family intake form on a phone

Parents fill in a form on their phone with two to four photos, the teacher sees every family on one page, and then we ask for one more question on the form.

  • DeepSeek V4.1 FlashWorks, with gaps

    Saved every answer and both photos on a two-page form, and the follow-up change landed. The build ran past the 15-minute limit.

  • GPT-5.6 LunaWorks, with gaps

    The most economical complete build: every answer and both photos saved. Its public assistant told a visitor a child's name.

One build per model. Read it as a direction, not a final rank.

DeepSeek · Tested Sep 2026

DeepSeek V4.1 Flash

The richest app per shape among the economical models. It built a six-page sales CRM whose scoring automation ran, a four-page match tracker, and a four-page cookbook with both automations live. On a family intake form it saved every answer and both photos.

  • Built a three-page match tracker whose coaching automation ran on the first match logged and wrote a note back into that match about six minutes later.
  • Built the richest sales CRM of the test, with six pages and a scoring automation that scored all 7 sample leads.

All DeepSeek V4.1 Flash results →

OpenAI · Tested Sep 2026

GPT-5.6 Luna

The most faithful model we have tested. It reproduced all 32 questions of a real customer's client sign-up form word for word again, built a scoring automation that ran, and passed every September follow-up-edit test.

  • Built a two-page match tracker in 8 minutes 19 seconds, the fastest and most economical complete build of its test, and a match saved from the app came back with all eight details in place.
  • Built the client sign-up form with four pages and a scoring automation that ran on its own.

All GPT-5.6 Luna results →

Interface, Task, Memory and Adapt are the four qualities TSK-1 grades: how finished the app feels, how closely it follows the request, whether it keeps your data, and how cleanly it handles follow-up changes. Read the method and every published test on the TSK-1 hub.

Open a live app built the same way

These are App Kits from the official Taskade account, not benchmark builds. Each one is a working app with projects, agents and automations, the same shape every benchmark request asks for. Open one, then clone it into your own workspace.

Browse all App Kits →

Verify the comparison yourself

This is our take. We’re biased: we make Taskade. Read the alternatives from the source:

When you are ready, build with Taskade Genesis or browse live apps from the Taskade community.

More Competitors & Alternatives

View All Alternatives ↗

Cursor

Codex vs Cursor in 2026: OpenAI's agentic coding system versus the AI-native code editor, with a per-task routing matrix, what Cursor's compute-based pricing actually buys, and the third path for people who want the finished app — Taskade Genesis.

Learn More

Cursor

Taskade Genesis vs Cursor in 2026. Cursor is one of the most-used AI-native code editors and ships new versions fast, the best-in-class agentic IDE for working engineers. Taskade Genesis is for the rest of the team (operators, founders, PMs), shipping deployed apps from one prompt with AI agents, workspace data, and 100+ bidirectional integrations included — and an AI allowance that comes with the subscription instead of being metered at API rates.

Learn More

Windsurf

Windsurf is now Devin Desktop — Cognition folded the IDE into the Devin product line and windsurf.com redirects to devin.ai. Taskade Genesis ships a deployed AI app workspace with built-in agents and 100+ integrations, so anyone on the team can use what gets built, not just the engineer who ran the prompt.

Learn More

Lovable

Codex Sites vs Lovable in 2026: OpenAI's Business-only, workspace-private app builder versus Lovable's full-stack code generator — with real 2026 pricing, an honest look at credit metering on both sides, and the prompt-to-app builder that publishes to the open web for everyone, Taskade Genesis.

Learn More

Lovable

The best Lovable alternatives in 2026, compared for people who ship business systems rather than codebases. Lovable is an excellent design-first builder that returns a React + Vite project you host and maintain. This page ranks eight alternatives by what you are actually building, states Lovable's real 2026 pricing with sources, and explains where Taskade Genesis fits: a running system with data, AI agents, automations, and app sign-in, with no deployment step.

Learn More

Lovable

Taskade vs Lovable, head-to-head for 2026. Taskade Genesis turns one prompt into a living app with AI agents, automations, and 100+ integrations you publish to the open web. Lovable generates React and Supabase code you deploy yourself.

Learn More

Bolt.new

Taskade Genesis vs Bolt.new in May 2026, after Bolt V2 (October 2025) Bolt Cloud + databases + hosting + Expo mobile, $40M ARR in 5 months, and StackBlitz's $105.5M Series B at ~$700M valuation. Bolt has the only browser-native WebContainers runtime in the category. Genesis ships deployed apps with AI Agents v2, 100+ bidirectional integrations, and Workspace DNA, flat $10/mo (billed annually) Pro, no token meter on bug fixes.

Learn More

Bolt.new

Taskade vs Bolt.new, head-to-head for 2026. Taskade Genesis ships a deployed app with AI agents, automations, and 100+ integrations from one prompt. Bolt.new generates React code in a browser sandbox, and Bolt Cloud now hosts it, but the app ships with no AI agents or automations.

Learn More

V0

Taskade Genesis vs v0 by Vercel in 2026 — after the v0.dev to v0.app rebrand, Figma and custom design-system import, the built-in Git panel, and agentic workflows. v0 ships best-in-class React/Next.js and shadcn code with the cleanest Figma-to-code path, now entering at Plus $30/user/mo with no annual billing. Taskade Genesis ships full deployed apps with a workspace backend, AI agents, and 100+ integrations on flat $10/mo billed annually.

Learn More

Imagine it. Run it live.

One prompt becomes a live app with agents, memory, and automations.